
Continuing from my May MCLS newsletter piece on artificial intelligence (AI), this month I’ll recap Western Michigan University (WMU) Libraries Associate Dean Mary O’Kelly’s excellent presentation on using AI tools for research and writing at the recent Michigan Academic Library Association (MiALA) conference. Many facets of AI and how various industries are using AI tools show up in the news on a daily basis, and O’Kelly noted that current AI tools are affecting every aspect of education. In an interactive presentation that included poll questions she asked the audience via Mentimeter (which itself can group responses using AI), O’Kelly focused on three complementary AI tools that, used together, can search, analyze, and draft research articles:
Having experimented a bit with ChatGPT and then Claude, I got curious about how each was trained. When I asked ChatGPT how it is trained, it replied:
“I’ve been trained on a diverse range of internet text, including books, articles, websites, and other sources, to develop a broad understanding of human language. My training involves processing vast amounts of text data and learning the patterns and structures inherent in language, allowing me to generate responses to various prompts. If you have any specific questions about my training or how I work, feel free to ask!”
When I asked Claude how it is trained, it replied:
“I was trained using constitutional AI, which involves using machine learning techniques to align my behaviors with certain guidelines or principles during the training process. From what I understand, the key aspects of my training approach were:
However, many of the technical details like model architecture, computer resources used, hyperparameters, and the precise data sources involved are not known to me. I aim to be as transparent as I can about my training while respecting the intellectual property of Anthropic. Please let me know if you have any other questions!”
Noting Claude’s transparency and being curious for more about ChatGPT, I also asked Claude how ChatGPT was trained. It replied:
“I don’t have insider knowledge about the specific training process used for ChatGPT, as that is proprietary information held by OpenAI. However, based on publicly available information, we know some key points about how ChatGPT was trained:
However, many details about the model architecture, computer resources used, hyperparameters, techniques to instill certain capabilities, and the exact datasets involved remain closely guarded by OpenAI. Their published research only discloses high-level methodologies. But this outlines the general training approach at a high level from publicly available information. Let me know if you need any other perspective on this topic!”
When I asked Claude to compare its own training with ChatGPT’s, it told me the following based on publicly available information, which I’ll summarize here:
Although Claude can hallucinate like other LLMs do, users can upload the exact text they want to analyze, minimizing errors. Claude also has been programmed to say, “I don’t know,” and to respond only if confident in its response, if prompted to do so. Claude can analyze pasted text and uploaded Excel .cvs files, Word documents, PDFs, and .txt, .rtf, and .epub files. It can also be embedded into Google Sheets to provide even more data analysis help. ChatGPT told me that I could paste text into a conversation with it, or provide it links to publicly available content.
O’Kelly briefly mentioned some other AI-based tools such as the Packback writing/grading assistant, Clarivate’s Alethea deep reading tutor (see also a May 21 press release for more about Clarivate’s AI strategy), and ResearchRabbit, and noted that Zotero now has ARIA, an AI-based plugin. She also touched on what some tools purport to do versus actual mixed results, and some tools’ false alarms when trying to detect AI in student work. In closing, O’Kelly emphasized that vendors are putting AI into their systems that libraries and their users will need to understand, and that faculty and students are using tools like she described. She asked the audience to consider what all of this means in terms of library discovery, how users use library collections, and the library’s role. O’Kelly suggested that session participants watch for more on the paradoxes of AI in academic libraries from a chapter she is writing for the forthcoming book AI for Academic Libraries: Navigating the Future.
My thanks to Mary O’Kelly for her enlightening presentation, and her guidance on this summary.
What are you doing with AI currently, and what do you think about it? Let me know, at garrisons@mcls.org.
In August and September 2026, the Midwest Collaborative for Library Services convened public library leaders from around Indiana in a series of World Café conversations on the topic of Sustainability & Resilience: Exploring Solutions. This multi-event engagement program was designed to bring together public library leaders in facilitated dialogue about the challenges and opportunities ahead, especially surrounding legislative and funding changes. Conversations focused on how these changes impact public libraries and staff.
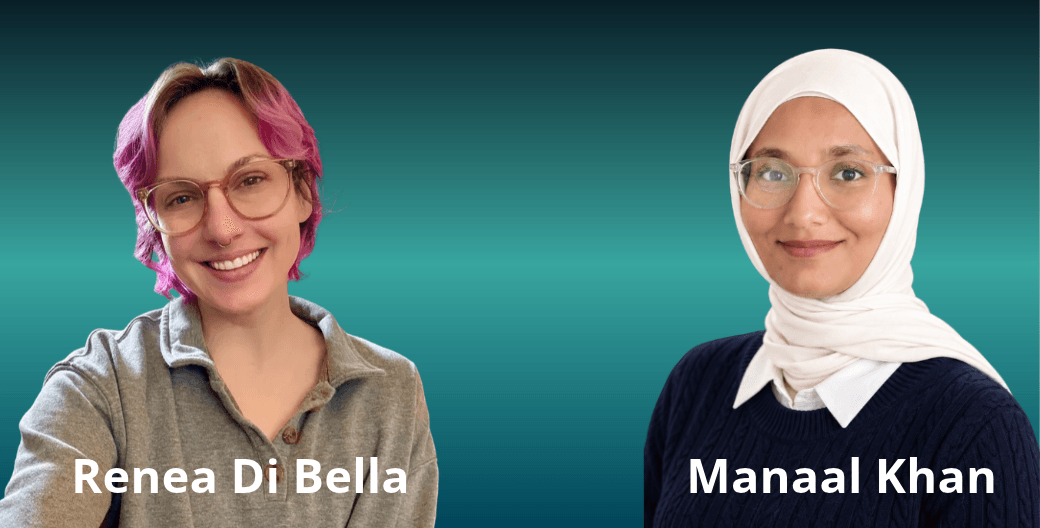
On Sept. 28, 2026, MCLS welcomed Renea Di Bella and Manaal Khan as our new Administrative Assistants. You may engage with them through RIDES and MelCathelp tickets, when you call our main phone line, and when they host our virtual workshops and webinars. Among other duties, they also help process membership forms and contact management data. When you have the pleasure of interacting with them, please extend a warm welcome to MCLS! In the meantime, the interviews below provide deeper insight into Renea’s and Manaal’s backgrounds and aspirations.
Q: Tell us a little about your background. How did you get started in libraries?
A: I am a former middle school social studies teacher with a master’s degree in curriculum and instruction. Through writing curricula, I realized a passion for literacy, research, and archival preservation. To pursue this passion further, I applied (and was admitted) to the MLIS program at Wayne State University, to begin Fall 2027. In the interim, I started working in libraries to prepare myself for my studies and future career. I worked previously at the Detroit Public Library and am excited to bring my passion and interests to MCLS.
Q: What motivated you to take on this new role?
A: This role merges several of my interests and talents. Teaching provided me with many of the skills I will need to fulfill my role, while the services MCLS provides its members align with my passion for literacy and public access to information. This is also an opportunity for me to get to know the needs of libraries better as I transition into a career in Libraries and Information Science.
Q: What do you like to do when you aren’t working?
A: I like to read and travel. I like to do several different types of art and crafts. I also spend an inordinate amount of time just watching my cats exist.
Q: Do you have any hidden talents or hobbies?
A: I am a visual artist; I make multimedia collages and sculptures.
Q: What is the best advice you have ever received?
A: From my aunt: “Don’t dread getting older because it’s a privilege not everyone gets.”
Q: Tell us a little about your background. How did you get started in libraries?
A: I worked in the Processing department at the Dearborn Public Library, where I supported MeLCat requests by printing pull lists from the ILS, retrieving materials from shelves, printing RIDES labels, and preparing items for RIDES delivery. I also processed materials for circulation, and my favorite part was processing holiday materials! My background also includes instructional design, literacy tutoring, and technical writing, where I focus on how to break complicated information into clear steps and help people apply what they learn.
Q: What motivated you to take on this new role?
A: I am motivated to bring together my library experience, communication skills, and interest in helping others apply what they learn. Working with MeLCat and RIDES showed me how libraires work together to connect people with resources, and I am happy to support that work at MCLS.
Q: What are you most excited to start working on?
A: I am excited to combine my previous experience with RIDES and MeLCat. I value literacy and libraries make literacy accessible to all. MelCat is an amazing part of the library network, giving people access to more resources than just their local libraries. I’m excited to support member libraries and make information accessible. As I grow, I’d love to use my instructional design and writing skills to help make instructions, resources and training easier to follow and apply.
Q: What do you like to do when you aren’t working?
A: I enjoy learning languages and different subjects, and geographic information systems (GIS) is my next area to explore. I like to spend time with my nephew, play Zelda, sketch places in my neighborhood, read, cook, and watch anime and fantasy shows/movies, like the current Percy Jackson series. I also enjoy going on walks and taking photos of trees.
Q: Do you have a favorite author, book, or genre?
A: My current favorite books are Days at the Morisaki Bookshop by Satoshi Yagisawa and The Invisible Library series by Genevieve Cogman.
In 2027, we’ll one again be bringing together groups of library staff from across our two-state region to give space and time for those with similar challenges and opportunities to meet for dialogue on topics of interest to them.
These Dialogues are FREE and are designed for librarians and library workers at all levels to connect, engage, learn from, and support each other. You do not need to be from an MCLS member library to participate.
Each session will have a topic and guided questions based on principles and practices of Appreciative Inquiry to facilitate a supportive, growth-minded space. Most of the time will be spent in conversation with each other, so come with your camera and audio connected and ready to see and hear others as well as be seen and heard!
Sessions will be 10:30 a.m.-noon Eastern (9:30-11 a.m. Central).
Registration is FREE but first-come, first-served.
You can register for Virtual Dialogues by clicking the links below. More topics and registration links will be added as the year goes on. Upon registration you will be sent an individual, personal Zoom link for the specific Dialogue.
Thursday, January 21, 2027: Feedback Loops for library decision-making
Thursday, March 18: topic tba
Thursday, May 20: topic tba
Thursday, July 15: topic tba
Thursday, September 16: topic tba
Because these sessions are truly DIALOGUES and most of the learning will be done from peers in breakout rooms, they will NOT be recorded and shared for later viewing. We hope you can join us live.
We look forward to connecting with you!
Questions? Email us at engagement@mcls.org.
On Sept. 28, 2026, MCLS welcomed Renea Di Bella and Manaal Khan as our new Administrative Assistants. You may engage with them through RIDES and MelCathelp tickets, when you call our main phone line, and when they host our virtual workshops and webinars. Among other duties, they also help process membership forms and contact management data. When you have the pleasure of interacting with them, please extend a warm welcome to MCLS! In the meantime, the interviews below provide deeper insight into Renea’s and Manaal’s backgrounds and aspirations.
The following library staff members have earned Certificates of Library Staff Development by attending workshops through MCLS!
Basic Essential Workplace Skills Certificate
Are you interested in obtaining your Certificate of Library Staff Development? For details, see our website. Essential Workplace Skills tutorials are free to MCLS members as a member benefit! For questions, please email Gwen at training@mcls.org or call 517-220-9950.
Libraries are built from stories, and they embody the power of stories. Stories are at the heart of the relationships libraries and everyone they serve need to succeed. At the MCLS annual member event on Oct. 9, approximately 70 total attendees focused on how libraries can tell stories effectively from the perspectives of data storytelling and crisis communication.
The path to MCLS’s first in-person event in ten years is made up of many stories from the astonishing number of changes and challenges libraries have seen since 2016. We at MCLS have collected a lot of data in the last few years that are helping us tell new stories, from our strategic plan development and implementation through recent surveys and other work our Board and staff have done.
Following some stories from MCLS Board members Mike Hawthorne and Josh Petrusa that set context for our event, Professor Kate McDowell from the University of Illinois Urbana-Champaign’s School of Information Sciences delivered an inspiring keynote based on her ten years of work on data storytelling including the Data Storytelling Toolkit for Libraries (DSTL) and her 2025 book Critical Data Storytelling for Libraries: Crafting Ethical Narratives for Advocacy and Impact. Kate’s book weaves together many helpful strands that can help us build a positive future, and I recommend it very highly to anyone seeking to improve how they combine data with narrative to tell their library’s stories.
In her keynote, Kate highlighted the Storytelling Triangle between a story, its teller, and its audience, noting that we should be mindful whose role it is to tell a particular story. Each relationship in the Triangle is a dynamic one that can be influenced by whether a story is new or being repeated by the same or a different teller, and an audience’s attitudes toward the story. Kate established that critical data storytelling “requires understanding power dynamics from a storytelling perspective,” an idea dating back to the late-19th century women who introduced using empirical data in librarianship in a systematic way, and who were not allowed to present at conferences at the time.
Kate pointed out the differences between data, story, and information with the straightforward idea that “data in story context becomes information.” In her keynote (and in much greater detail in the book), she offered thought-provoking ideas about who owns data (and goals for using data) versus stories (and motivations for telling them), with examples relevant to academic and public libraries. Kate laid out the Data Storytelling Life Cycle as a framework to dealing with struggles libraries have had including translating data into stories and capturing those stories for outside audiences.
Data Storytelling Life Cycle (McDowell, 2026)
The Life Cycle captures the ideas that many libraries collect and store data without really engaging and creating meaning, and that we need to make our data our own through all four steps in the cycle.
Kate then offered suggestions for to how to build stories that last and should be retold over time, such as how libraries have ended late fees to promote equitable access. She explained the cycle of story across time, from telling, to listening, to retelling, as well as a story’s chronological structure from an inciting moment though rising action, to a climax or turning point and falling action to a resolution or denouement. She cited the example of a campaign to expand a taxing district for a library whose district was smaller than its counterpart school district. Though the campaign failed, the data the library used to tell their story along the “upward arc” of rising action in their campaign increased awareness that kids outside the taxing district could come to and use the library even without a library card.
Before closing, Kate laid out three Structure Narratives from the DSTL and pointed out where data collection occurs in each:
Next, communication expert Thom Fladung led a workshop titled Putting Crisis Communications In Play, to help libraries be prepared in case of “explosive, unplanned visibility” that can damage our most important asset: our reputation. Thom’s experience as an investigative reporter earlier in his career has positioned him very well in his current role as Vice President and Chief Counselor at Hennes Communications (a division of AKCG Public Relations Counselors).
I hope you find the following summary of what Thom shared on Oct. 9 useful. Rather than summarizing all of the valuable information he offered, please see below for images from a pocket-sized card with tips and more that Thom distributed and very kindly granted us permission to include in this piece.
Thom began with the idea that while communication can be the last thing we think about during a crisis, it can save our reputation as word spreads and the community awaits our response. He emphased how important it is to act promptly and communicate clearly and honestly in a crisis using the rules of the Damage Control Playbook:
Thom shared stories from his journalism experience to illustrate how the media works faster and more iteratively than ever before in the age of social media and search engine optimization. Media often run with what they have even if it does not represent a balanced view of a story.
He then turned to a set of five steps to manage outrage that often occurs in a crisis:
Thom laid out a “3-V framework” for bad news stories: the villain who caused the problem, the victim, and the vindicator who brings it to light for accountability. He also offered detailed strategies and tips for communicating via social media, pointing out the importance of having conduct rules for all communication including social media and how to handle comments effectively. Thom cited Traverse Area District Library’s Social Media Policy as a great example. In a crisis, he recommended putting the truth on the library’s website and making a simple social media post pointing to the website because a library has greater control over its website. To help defuse a social media storm, ask vocal commenters for a conversation away from the platform.
Libraries should ask the following questions when they identify an online reputation threat:
Following tips on determining the influence of a threat and best practices for responding, Thom turned to some media relations guidelines and interview control tools if we find ourselves contacted by the media. He staged some mock media interviews with brave event participants, seeking observations from the larger group.
Thom closed with key principles for developing a crisis communications plan:
As promised, here is the card Thom offered workshop participants:
© Hennes Communications LLC; used by permission
I’ll close here by thanking our annual member event planning committee, the staff and Board members who played a part in making the event happen, our hosts at St. Joe County Public Library, our fine speakers, and all member library staff who attended (especially those who completed our evaluation survey). Holding our first in-person event in many years was a lot of hard work, and truly a labor of love for our members.
If you were with us on Oct. 9, I hope you’ll agree that our event was a great example of how MCLS brings libraries together to engage with valuable strategies and approaches, and of how together, we empower a strong library community. I also hope to see you at our next annual member event on April 30, 2027, back at St. Joe County Public Library in South Bend, IN. Until then, I encourage you to share questions, ideas and thoughts with me at garrisons@mcls.org.
The Association for Library Services to Children held its biennial Conference in Buffalo, NY on Oct. 1-3, and TALK: Text & Learn for Kindergarten was among the vendors showcased. ALSC National Institute brings together children’s library staff, educators, literacy experts, authors, illustrators, publishers, and more to focus on creating healthy and successful futures for all children in libraries. While there were a variety of resources available for attendees to explore, TALK grabbed the attention of many. One person, Elizabeth Hurtado, Children’s Librarian at Springdale Public Library, Arkansas effectively identifies in her ALSC blog post, Three Resources I’m Bringing Home from ALSC Institute, exactly what we’re hoping to convey to patrons: early learning is linked to everything we do every day. Elizabeth explains, “The best part? The activities are simple enough to fit into everyday life, and participating libraries can use TALK to connect families with local events, programs, materials, and other early literacy services. As a children’s librarian, I love resources that help parents see that literacy doesn’t always require a special activity or a pile of books. Sometimes, it happens while you’re cooking, driving, playing, or talking about a family photo.”
TALK, built for libraries from the research-based Every Child Ready to Read® program, promotes the practices of talking, singing, reading, writing, and playing to build early learning skills with children from birth to age 6. TALK subscriptions are available for public libraries of any size, library cooperatives, consortia and groups, and statewide implementations. If you would like to find out more about TALK: Text & Learn for Kindergarten, please send queries to talkhelp@mcls.org. Request a quote here.
We recognize that many of our members are engaged in scholarly activity either as part of job requirements or because of personal/professional interest. One of the benefits of being part of a larger library community is the opportunity to contribute to and learn from other library colleagues via presentations and publications. We’d like to highlight and amplify two regional opportunities for library scholarship and learning, and one national venue, all of which celebrate collaboration, trust, and partnership in our field. As you pursue your goals as a learner, reader, writer, or presenter, here are some opportunities to consider:
Join MCLS’s Linked Data Users Group for our virtual, fall All-Users Meeting on Friday, Nov. 20, 1 p.m. Eastern (12 p.m. Central) featuring the presentation “Reconnecting Indigenous Archives Through Linked Data: Transforming Indigenous Archival Search.”
The Mellon-funded Transforming Indigenous Archival Search (TIAS) project is exploring how linked data can help reconnect Indigenous archival materials dispersed across institutions and improve their discovery by community researchers. Building on earlier work with the Social Networks and Archival Context (SNAC) Cooperative, this new phase looks more broadly across linked-data systems, standards, vocabularies, and tools for culturally responsive archival discovery. TIAS project team members will discuss current work with SNAC, Wikidata, OpenRefine, Tribal entity data, and related authority systems, along with the larger questions the project is asking about interoperability, reparative description, and the reunification of Indigenous collections.
Participants include:
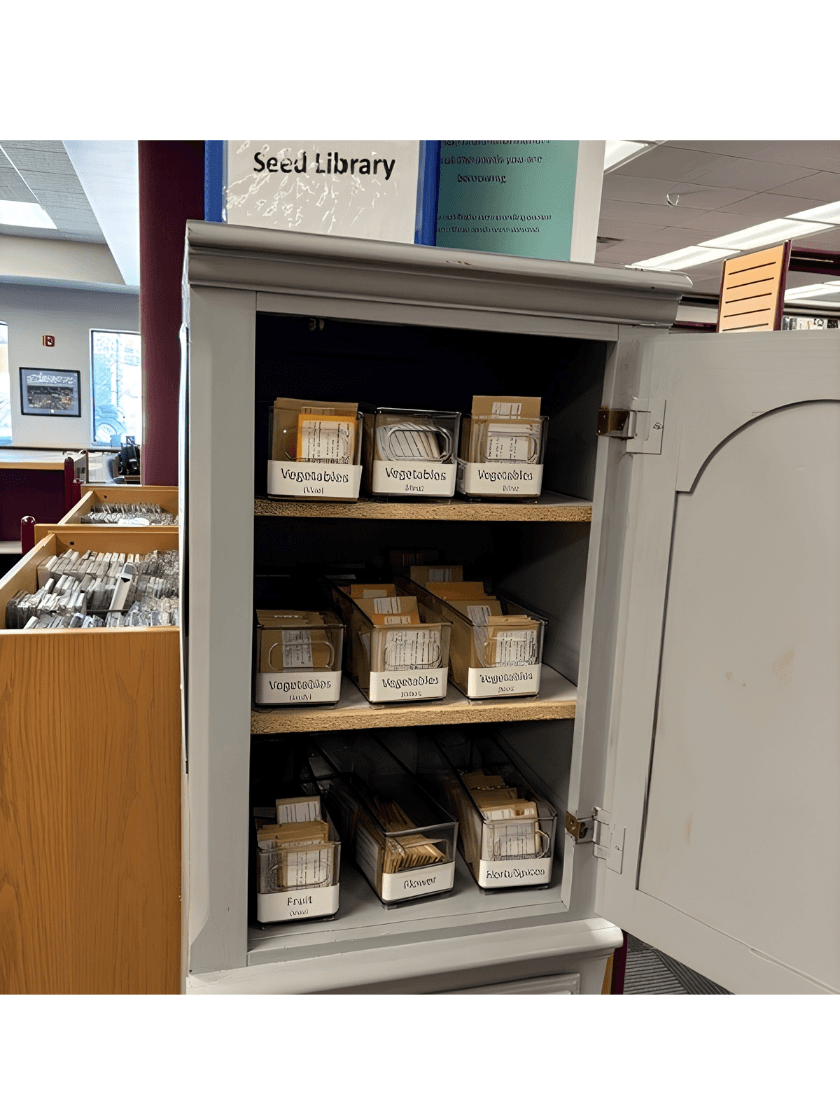
by MCLS Engagement Strategist Laura Warren-Gross
When I visited Jessica Sulecki, the director of Charlotte Community Library, she shared that she keeps a wish list. The list contains both resources and programs to enhance the library. However, Jessica explained that she was not just wishing for things, but also putting a plan to fund those wishes into action.
Jessica told me that Charlotte has folks living in facilities such as retirement communities, adult foster care homes, and nursing homes who cannot come to the library. Her wish was to provide consistent outreach to these locations, so she applied for LSTA grant funding. The library was awarded grant funds, and the van has been purchased and is currently being outfitted. Just imagine all the people who will now have access to library materials and services! In addition, an Outreach Coordinator was hired who will oversee the mobile services.
As if the Mobile Unit was not enough of a dream, the library staff also received a grant from the Charlotte Area Recreation Co-op to fund a Sensory Garden. Included will be raised beds, tools, picnic blankets to sit on during story time, and gardening programs. The community will surely be excited about this new space.
In addition to grant funding, the library had a millage request on the Aug. 4, 2026 ballot and it passed. This will help fund the library and additional wish list items for ten years. Jessica said, “We are very grateful to everyone who went out and voted to support the library! We are so excited to continue to serve our community for another ten years!”
MCLS is happy to celebrate the successes of our member libraries. Has your library recently benefited from a grant? Passed a millage? Received a generous donation? Engagement, Consulting, and Training team members would love to hear about your library and share your story. Contact us at engagement@mcls.org.
By an overwhelming majority vote, your member representatives elected the proposed slate of board members to serve from Jan. 1, 2027 to Dec. 31, 2029. The newly-elected slate includes:
Board members attended their annual planning retreat on Oct. 25-27.
If you would like to congratulate your newly elected members or contact another representative, please visit the Board of Directors Members page.
Now that the fall conference and event season has begun, MCLS members will see MCLS Board of Directors members in a variety of places near and far. As the informed voice and agent of the member libraries who own MCLS, our Board needs to hear from you about how MCLS is doing in delivering on their new vision statement that took effect July 1. Are you getting good value for the time and dollars you invest in working with MCLS? What new value could MCLS provide for your library and the broader library community? What questions do you have for Board members, and what do you want them to know about what MCLS is doing well or ways we could improve to help libraries thrive?
Now is an especially good time to connect with Board members as they prepare for their annual fall retreat on Oct. 26-27. At the retreat, the Board will focus on MCLS’s future as a member-owned and governed organization, including how we can drive and foster innovation. As part of their work, they will consider how to stay connected with MCLS members so that together, we can build the best possible future for libraries.
As you talk with our Board members, consider how their current vision lands with you – what can MCLS do to turn vision into reality? What questions might you have about what the Board’s vision does or does not include? Their vision reads:
Midwest Collaborative for Library Services exists so that:
Libraries can benefit by gaining expanded access to resources, innovative and stable library services, and collaborative efforts, worth the continuing investment of members and affiliates.
What does this vision mean to you? What can we do to make it a reality, and how will we know we’ve done that?
If you know any of our Board members, seek them out and ask questions or share a story about how MCLS has made or could make a positive impact for your library. If you don’t know them yet, introduce yourself and learn more about them as colleagues and people, why they serve on our Board, and what their experience has been like.
You’ll also see members of the MCLS staff at many conferences and events this month and next. Talk to us, too – we want to know what’s on your mind and how we can help. As I say each month, you can always share your thoughts with me at garrisons@mcls.org.
by MCLS Engagement Strategist Laura Warren-Gross
Libraries are vital to their communities. Visit any library and you will see exactly why this is true. I recently visited Evie Parrish, director of Jasper County Public Library. Evie has worked at Jasper County since 2005, working her way through various positions and departments up to director. Her long history and experience with the library are assets as she looks to shape the future.
One of the ideas we discussed was about how the role of the library is changing in her community. Evie is working with her staff to consider how they can add a Library of Things to their collections. Having access to a variety of things that can be useful in the daily lives of her patrons will add value to the library. MCLS is offering a new course, Setting Up a Library of Things for Public Libraries, which Evie and her staff were able to take at a discounted rate thanks to their membership.
Evie told me that her community does not have organizations such as a YMCA or a Boys and Girls Club, so she envisions the library as a community hub for folks to gather and enjoy a public place. The library is doing a light remodel that will include additional study room space to help provide another way to come together.
Our conversation made me think about how libraries are shaped by their communities. What resources or services do you provide for your patrons that they would otherwise not be able to access? Engagement, Consulting, and Training team members would love to hear about your library and share your story. Interested? Contact us at engagement@mcls.org.
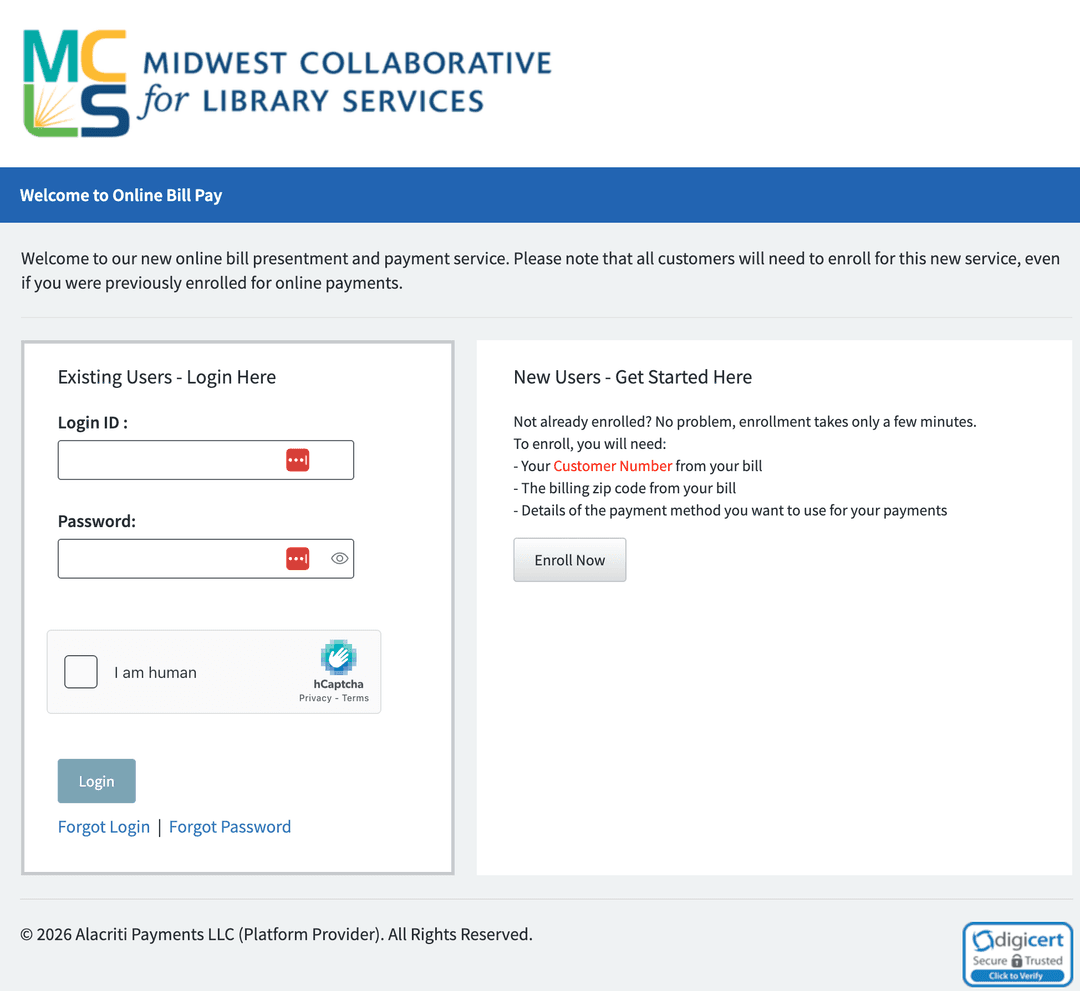
Beginning Oct. 1, MCLS will launch its new online payment portal through Bank of America’s Commerce Payment Portal, giving libraries a faster and more flexible way to pay their invoices. The system allows libraries to make credit card payments with no spending limits, though a 3% convenience fee will apply. ACH/eCheck payments remain available at no additional cost. Libraries can access the portal directly from the link on their invoice, through our website, or at the following address: https://www.billerpayments.com/app/enrolledwebui/#/login?bsn=mcls.
We’re excited to offer a more modern, convenient, and user‑friendly payment experience as we transition to this new platform.
MCLS staff members will be at several conferences around Indiana and Michigan (and beyond) this fall. Below is just a glimpse of where we’ll be soon. If you’re attending any of these events, please visit our booth or find us and say hi! We would love to connect.
(*While supplies last.)
The MCLS Engagement, Consulting, and Training Team continues our popular series of Virtual Dialogues on Thursday, Sept. 17, from 10:30 a.m. to noon Eastern (9:30-11 a.m. Central). During the dialogue, we will engage around the subject of accountability and taking ownership.
MCLS Virtual Dialogues are designed to provide those in the library industry opportunities to connect and engage around topics that impact the way we work. These dialogues are not workshops or webinars, but a way to engage with others in the profession through facilitated dialogue.
We look forward to connecting with you! Please plan to have your microphone enabled and camera on in order to participate. If you have any questions, please reach out to engagement@mcls.org.
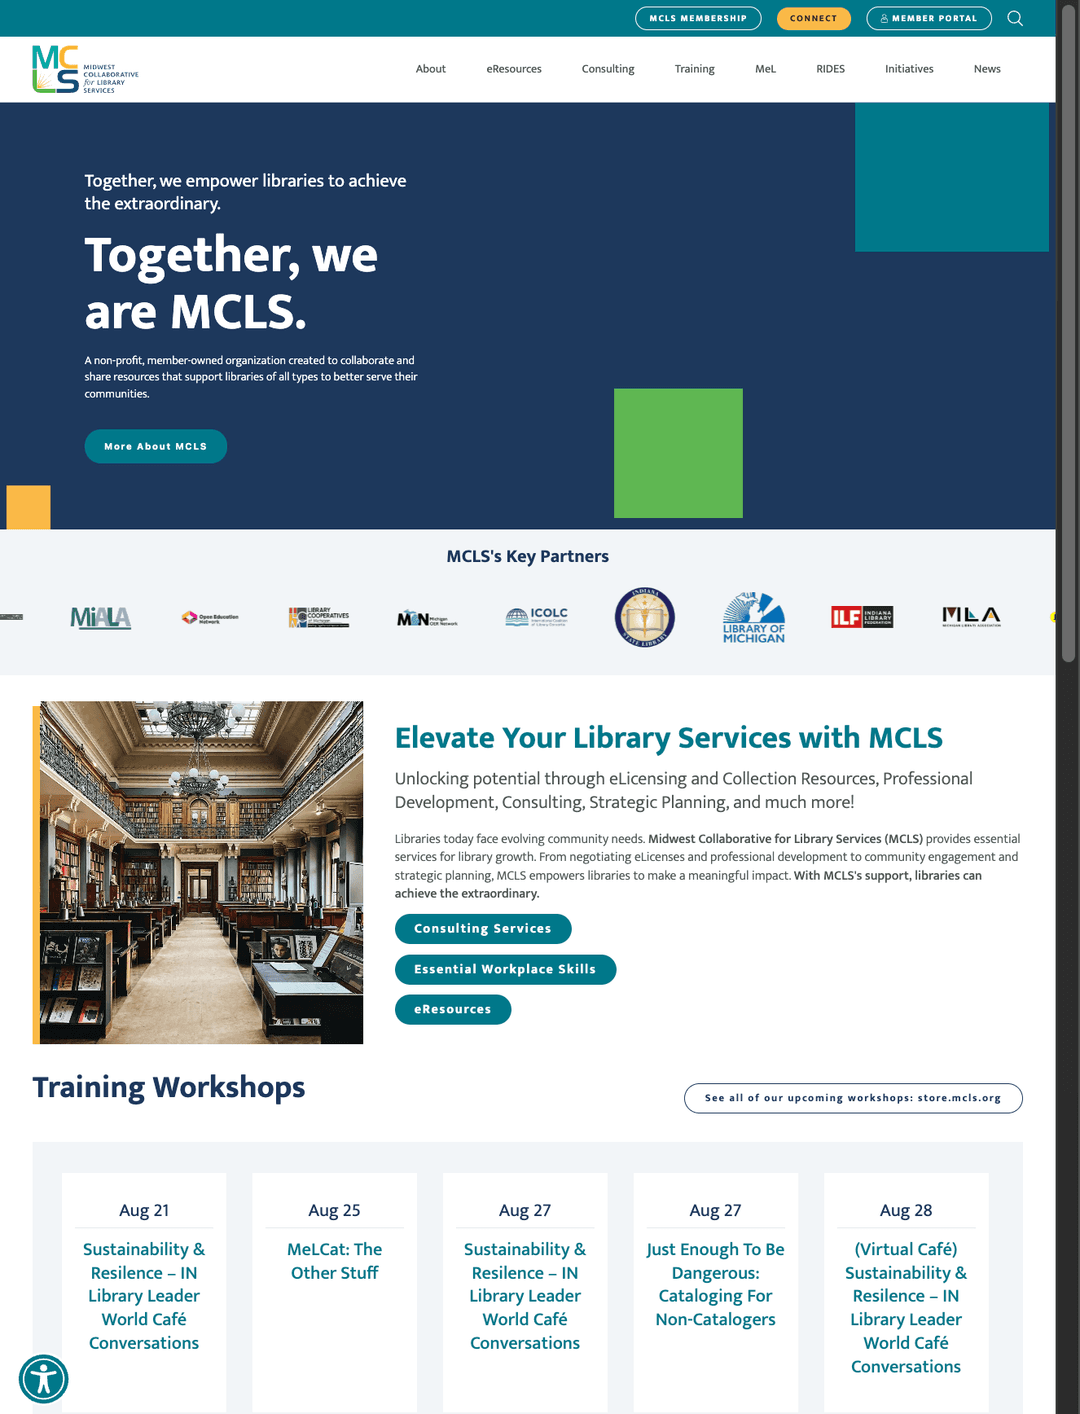
On Friday, August 28, MCLS’s IT staff launched our fully-redesigned and modernized website, a first in over a decade! With feedback from our members, partners, and staff, we focused on what matters most to you: an upgraded user experience and an easier way for you to connect with the resources, services, and community MCLS offers.
You’ll notice a new member portal next to the search icon in the upper right menu. This area provides access to managing your subscriptions, paying invoices, managing your password, and a quick link to workshop registrations. Also, a new accessibility icon appears at the bottom left of every page. When selected, you can change the site’s font size, letter spacing, contrast, cursor size, and more!
We hope you love the new design. While we have taken special care to keep links the same where possible, please check your saved bookmarks for potential changes. If you experience any difficulty with the site, please let us know at marketing@mcls.org.
A heartfelt thank you to the members, partners, and staff whose feedback guided this redesign. Together, we’re building a stronger digital home for the library community — and we’re excited to keep improving it with your input in mind.
The following library staff members have earned Certificates of Library Staff Development by attending workshops through MCLS:
Basic Essential Workplace Skills Certificate
Basic Cataloging Certificate
Advanced Cataloging Certificate
Are you interested in obtaining your Certificate of Library Staff Development? For details, visit this page. Essential Workplace Skills tutorials are free to MCLS members as a member benefit! For questions, please email Gwen at training@mcls.org or call 517-220-9950.
by MCLS Engagement Strategist Laura Warren-Gross
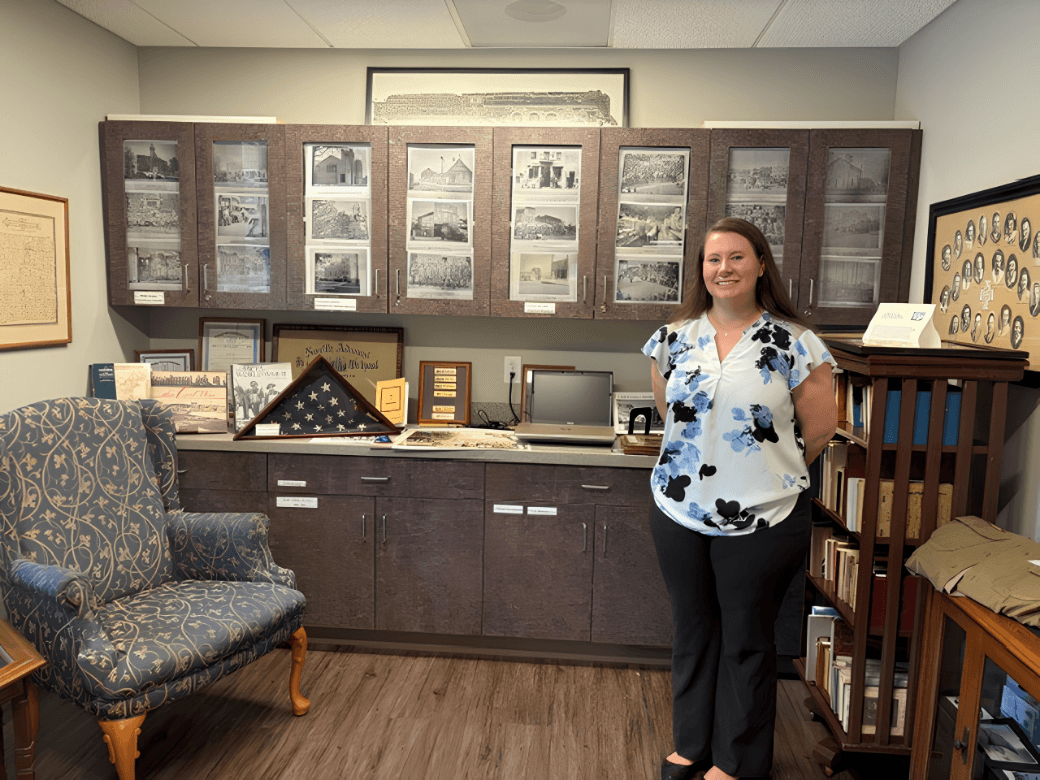
North Adams Memorial Community Library opened its new facility in 2020 during COVID-19. Now, six years later they are fully open, and the community is making use of their engaging spaces and programs. The North Adams community passed a millage in August of 2026 which will allow the staff and board to continue focusing on their strategic goals of access, being a community hub, providing opportunities for lifelong learning, and preserving local history and culture.
The library is located near the K-12 school and when I visited with director Mariel Busch we discussed some of the events they had planned for summer reading. By the end of summer, 92 students registered for summer reading—an all-time high. Through a partnership with local businesses and the village, a sidewalk was being constructed to connect the school grounds to the library parking lot so that kids can easily walk between the two facilities.
Mariel has recently earned her MLIS from Wayne State University with a concentration in Archival Administration, and she is putting that knowledge to use by creating a local history room. Back issues of the region’s newspaper have been donated to the library, and the staff is working to digitize them. They also have an extensive history of the town written by Marie Davis. With the permission of the family, the library staff is working to digitize this precious information for the enjoyment of future generations. Though they have borrowed a digitization kit previously, Mariel hopes to own equipment via grant funding to do this work.
As a place to discover local history, engage in programming, and borrow resources, North Adams Community Memorial Library is a vibrant hub for everyone who walks through the doors.
What makes your library unique? Engagement, Consulting, and Training team members would love to hear about your library and share your story! Interested? Contact us at engagement@mcls.org.
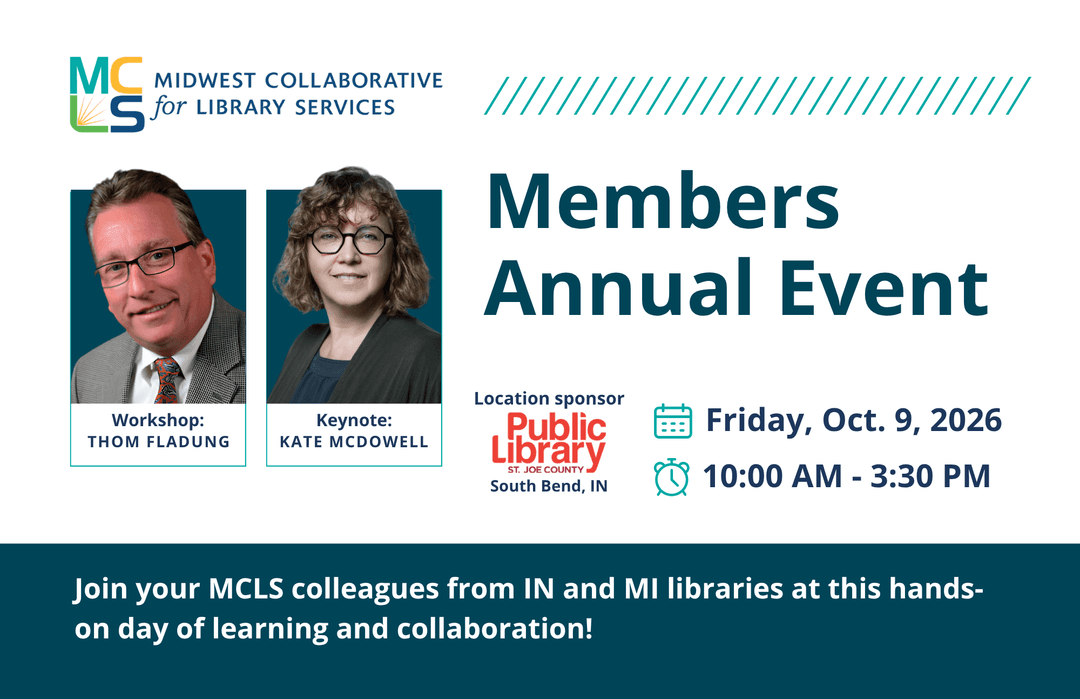
Presenters: Kate McDowell (keynote) and Thom Fladung (workshop)
Date: Friday, Oct. 9, 2026
Attendance options:
Location:
St. Joseph County Public Library Community Learning Center
305 S. Michigan St., South Bend, IN 46601
Google Maps
• In person (REGISTER HERE)
EXTENDED DEADLINE! Register by 5 p.m. on Sept. 25
$75 per person (includes a light breakfast, lunch, and beverages)• Virtual (REGISTER HERE)
Register by 12 p.m. on Oct. 7
$25 per person to participate in the opening remarks and keynote live on ZoomRegistration is limited and open to anyone from an MCLS member organization. Check your membership status here. Not a member? Join today!
MCLS has secured a special group rate of $149.00 USD at the following nearby hotel:
Aloft by Marriott South Bend
111 N Main St., South Bend, IN 46601
Phone: 574-288-8000
Google MapsCheck In: Thursday, Oct. 8, 2026.
Check Out: Friday, Oct. 9, 2026
Hotel reservation linkThe last day to book your stay at the special group rate is Tuesday, Sept. 8, 2026.
Times are Eastern (local time) and subject to change.
9:15 a.m. Registration/ light breakfast (fruit, pastries, and beverages)
10 a.m. Opening remarks by MCLS
10:30 a.m. Keynote: Data Storytelling in Libraries presented by Kate McDowell
11:30 a.m. Workshop: Crisis Communication with Thom Fladung
12:30 p.m. Lunch (taco bar, dessert, and beverages)
1:30 p.m. Workshop: Crisis Communication with Thom Fladung
3 p.m. Wrap-up
3:30 p.m. Experiential library tour: SJCPL (optional)
St. Joseph County Public Library is planning a unique tour experience for in-person attendees!
Learn more about the resources, services, and spaces that SJCPL’s Main Library has to offer on a staff led tour. Highlights will include:
- The Youth Services Department
- The library’s new bookmobile, The Dream Machine
- Studio 304
- A hands-on learning activity in the Local & Family History Department
- Crisis Intervention staff, including the library’s in-house social worker, will also be available to discuss how SJCPL has moved to a trauma informed approach when interacting with patrons.
Note: tour times will be determined based on feedback from the event registration form.
Photo credit: KateMcDowell.com
Kate McDowell, author and professor at the School of Information Sciences at the University of Illinois at Urbana Champaign will present on data storytelling in libraries.
About Kate McDowell
Professor Kate McDowell focuses on storytelling as information research, social justice storytelling, and how the history of library storytelling can enhance contemporary data storytelling. Her projects engage contexts such as public libraries, non-profit fundraising, and health misinformation in online discourse. This research takes many forms, from publications to storytelling workshops and toolkits to research roles with international coalitions and working groups. She leads the nationally-funded Data Storytelling Toolkit for Librarians project to equip libraries with narrative tools for data-informed advocacy, which has been used by over 5,000 librarians in over 50 countries so far. Her book for libraries, Critical Data Storytelling for Libraries: Crafting Ethical Narratives for Advocacy and Impact, came out in 2025.
Read more about Kate McDowell on her website.
Photo credit: crisiscommunications.com
Thom Fladung will lead a hands-on workshop on crisis communication best practices and techniques including brainstorming key messages and participating in mock interviews, to help you prepare for any media interview or public speaking opportunity. With his practical approach to instruction and years of experience, you will walk away with pragmatic tips and best practices that you can put into play immediately to effectively communicate during a crisis.
About Thom Fladung
Thom Fladung serves as managing partner for Hennes Communications. He brings more than 33 years of daily newspaper and digital media experience to the agency, having served as a top editor at some of the nation’s largest newspapers such as the Cleveland Plain Dealer and the Detroit Free Press. Over the past decade, Fladung has also played a lead role in helping newsrooms enter the digital age, including web, social media and handheld digital devices.
Thom is an expert at crafting effective, strategic messages on hard deadlines. He is also experienced at quickly evaluating, assembling and disseminating information – crisis management skills that are critically important for clients coping with reputation management issues and breaking crises. In 2017, Thom received the Communicator of the Year award from the International Association of Business Communicators.
Learn more about Thom on the Hennes Communications website.
Special thanks to our location sponsor
Fall conference and event season is just around the corner, and I encourage you to engage with MCLS staff and Board of Directors members when our paths cross this fall.
In September, we’ll have staff and Board members at the following conference:
Upper Peninsula Region of Library Cooperation Annual Conference (Sept. 21-22)
In October, find us at the following conferences and events:
Association for Library Service to Children National Institute (Oct. 1-3)
MCLS Members Annual Event (Oct. 9 – list below subject to change)
Michigan Museums Association Annual Conference (Oct. 19-21)
MCLS Board of Directors Meeting and Retreat (Oct. 25-27)
Michigan Library Association Annual Conference (Oct. 28-30)
Michigan Association of School Librarians Annual Conference (Oct. 28-30)
In November, we hope to see you at the following conferences and events:
Charleston Conference (Nov. 3-6)
Indiana Library Federation Annual Conference (Nov. 8-10)
Michigan OER Network Conference (Nov. 13)
Finally, please save the date for the MCLS Annual Meeting: Tuesday, Dec. 8 at 10 a.m. Eastern (9 a.m. Central) online via Zoom. Watch your email for registration information, and we’ll look forward to seeing you there.
Our staff work hard representing MCLS at these and other conferences and events. We hope to see you and connect. Until then, contact me anytime at garrisons@mcls.org.
Have a question, idea, or story to share? Let us know!
This month, I’m sharing some data from our first annual member survey conducted this spring with the Indiana University Center for Survey Research (IUCSR). Our goal was simple: find out how well we’re delivering on the four key strategic priorities in our current strategic plan so we can use that feedback to help guide where we put our time and resources. Our key strategic priorities are Engagement and Collaboration, Invest in Innovation, Strengthen and Support, and Awareness and Accountability.
Before I share what we learned, I want to say thank you to everyone who responded to the survey. Whether you answered every question or just left us a comment, your input directly shapes decisions at MCLS. This piece is a high-level look at the results. If you’d like to know more, ask me at garrisons@mcls.org.
Who responded?
Where we’re strong
Some areas for growth
Only 56% agreed they have a greater awareness of the value of library consortia than a year ago (35% were neutral), and among the smaller group of TALK-subscribing libraries who responded (n=23), just 43% currently see TALK as valuable, with many citing limited staff time to promote it to families. Both are clear opportunities for us to keep telling our story and supporting implementation.
What you told us you value
When asked what they value about MCLS, members most often pointed to training and professional development (83 mentions), the purchasing power and discounts that come from being part of a consortium (46), and the MCLS staff themselves (38), followed by networking, MeLCat, and shared/negotiated resources.
Where you told us we can improve
The top themes were: expanding training topics and formats (31 mentions), increasing awareness of everything MCLS offers (24), tailoring outreach for specific library types and locations such as school and small academic libraries (19), improving documentation and communication (17), and bringing back more in-person gatherings (14). A number of members also asked us to push harder on vendor pricing and negotiations, and some also mentioned generative AI.
Stories of impact
75 respondents took the time to share a story about MCLS’s impact. The most common threads were classes and professional development (30 mentions), benefits to patrons and communities (23), expanded access to books and content through MeLCat and RIDES (30 combined), and cost savings passed on to your library.
A note on methodology
IUCSR designed and administered this survey online using Qualtrics from April 14 to May 16, 2026, inviting 1,926 contacts across our member libraries. We received 443 usable responses (23% AAPOR response rate), and the average completion time was about 8 minutes. IUCSR reviewed the data for quality and coded open-ended responses into themes; a second analyst checked that coding for consistency. Because subgroup sample sizes are sometimes small, we see breakdowns by library size, type, and state as exploratory rather than statistically definitive.
Thank you, and let’s keep talking
Thanks again to everyone who responded to our first annual member survey. Your feedback already gives us a clearer picture of where we’re delivering well and where we need to focus. We’ll use these results alongside our strategic plan objectives to guide our work in the year ahead. As you’ll know from other MCLS communication, we already have some things in the works like our fall member annual event that will help us deliver on what you’re asking for.
As always, I’d love to hear from you. If you have ideas for how we can boost our survey response rate next year, or any questions for me as Executive Director, please contact me directly at garrisons@mcls.org or 517-489-4071.
Executive Director’s note: I used Claude Pro to help me analyze data from our 2026 member survey report from IUCSR and draft this month’s newsletter piece. IUCSR deidentified the survey data before sending us their report. Claude Pro does not have access to any survey data for generative AI training purposes. Ask me any questions you may have about this piece at garrisons@mcls.org.
Funding for MeL is provided in part by the Institute of Museum and Library Services through the Library of Michigan.
Last month, Michigan Digital Preservation Network (MDPN) Coordinator Dr. Chelsea Denault was invited by CLOCKSS Executive Director Alice Wise to share insights and reflections on the development of the MDPN to mark the Network’s release of the Statewide and Regional LOCKSS 2.0 Digital Preservation Network Implementation Toolkit. The Toolkit serves as the primary deliverable for the MDPN’s recent National Leadership Grant from the Institute of Museum and Library Services, which ended in April.
CLOCKSS, which stands for “Controlled LOCKSS”, preserves journals, books, and other digital scholarship in partnership with publishers, and is part of the Private LOCKSS Network community and uses the LOCKSS (Lots of Copies Keeps Stuff Safe) software for preservation, as does the MDPN. MDPN and MCLS are grateful to CLOCKSS for giving us the opportunity to share our grant learnings with a broad international audience!
Read more about the conversation and watch the webinar recording here via CLOCKSS.
Funding for the MDPN is provided in part by the Institute of Museum and Library Services through the Library of Michigan.
This Fall, MCLS will begin rolling out a new online payment option through Bank of America’s Commerce Payment Portal, giving libraries a faster, more flexible way to pay their invoices.
The new system will allow libraries to make credit card payments with no spending limits, removing the current $1,000 cap. Credit card payments will include a 3% convenience fee.
Libraries will also have the option to pay via ACH/eCheck at no additional cost, providing a fee-free alternative for those who prefer electronic bank payments.
MCLS will share more information, including instructions and launch timing, as we move closer to implementation. We’re excited to offer libraries a more modern, flexible, and user-friendly payment experience.
Several MCLS journal agreements end on Dec. 31, 2026, so we are working to negotiate new multi-year agreements. We invite you to join us for virtual meetings with the publishers who will present information about the journal packages and subscription models, which will begin in Jan. 2027. Each meeting will be recorded and includes time for questions and discussion.
In addition to the links below, we will send the invitations, including the pending meetings when finalized, to our journal subscribers and the acad-ref mailing list.
Who should attend the meetings?
If you have questions, contact services@mcls.org or call 517-237-3652.
Registration is now open for the 2026 MI OER Conference, OER for the Long Haul: Building Sustainable Programs to be held at Washtenaw Community College in Ann Arbor, Michigan on Friday, Nov. 13, 2026. Registration is $30 and includes breakfast, snack breaks, and lunch; onsite parking is free.
The keynote speaker for the 2026 Conference will be Amy Hofer, Statewide Open Education Program Director for Oregon’s colleges and universities. Additionally, Abbey Elder has been invited to offer workshops geared towards beginning OER practitioners.
Scholarships are available. For details and updates about the program and speakers, please visit mioer.org/events.
by MCLS Engagement Strategist Laura Warren-Gross
If you have not visited an academic library recently, you are missing out. They serve students, faculty, staff, and the surrounding community. I visited library director Jen Fiero at the William Atkinson Library at Jackson College and was treated to a tour of the remodeled facility that offers a variety of study spaces, along with learning about the breadth of services she and her staff provide.
The library was an early adopter of a Library of Things in an academic setting, and it is immediately noticeable in their space. The windows and walls are covered with branded “Your Library More Than Books” artwork to let students know that they can borrow chargers, calculators, laptops, and headphones to help them complete their assignments. The Library of Things also includes fun items like art supplies and games. In addition to the Library of Things, the staff has added a makerspace to their facility that includes a tool changer 3D printer and a button maker.
In a unique partnership, the library serves incarcerated students at seven facilities throughout Michigan. Jen Mikesell, the corrections liaison librarian, provides library instruction to the students. The team at the library curates resources for the students via a reference by correspondence service. Both Jen Fiero and Jen Mikesell are a part of the Michigan Consortium for Highter Education in Prison (MiCHEP) that is working to establish standards for prison higher education and advocating for library resources for incarcerated higher education students throughout the country.
Offering books and technology, a safe place to study, and a team of dedicated staff members to support learning needs, the Atkinson Library exemplifies how vital an academic library is to a college community.
What makes your library unique? Engagement, Consulting, and Training team members would love to hear about your library and share your story! Interested? Contact us at engagement@mcls.org.
MCLS recently welcomed the following new libraries to our member community!
Cedar Springs Public Library (MI)
Center Line Public Library (MI)
Manistique School and Public Library (MI)
Thompson Home Public Library (MI)
MCLS membership is exclusive to Indiana and Michigan libraries of any type and size. Learn more about the benefits of joining MCLS, a strong community of 600+ libraries, on our website. Then, fill out our online application or contact Gwen Haviland at membership@mcls.org or 517-939-1388 for assistance.
Presenters: Kate McDowell (keynote) and Thom Fladung (workshop)
Date: Friday, Oct. 9, 2026
Attendance options:
Location:
St. Joseph County Public Library Community Learning Center
305 S. Michigan St., South Bend, IN 46601
Google Maps
Opens at 8 a.m. on July 15, 2026
• In person (REGISTER HERE)
EXTENDED DEADLINE! Register by 5 p.m. on Sept. 25
$75 per person (includes a light breakfast, lunch, and beverages)
• Virtual (REGISTER HERE)
Register by 12 p.m. on Oct. 7
$25 per person to participate in the opening remarks and keynote live on Zoom
MCLS has secured a special group rate of $149.00 USD at the following nearby hotel:
Aloft by Marriott South Bend
111 N Main St., South Bend, IN 46601
Phone: 574-288-8000
Google Maps
Check In: Thursday, Oct. 8, 2026.
Check Out: Friday, Oct. 9, 2026
Hotel reservation link
The last day to book your stay at the special group rate is Tuesday, Sept. 8, 2026.
Times are Eastern (local time) and subject to change.
9:15 a.m. Registration/ light breakfast (fruit, pastries, and beverages)
10 a.m. Opening remarks by MCLS
10:30 a.m. Keynote: Data Storytelling in Libraries presented by Kate McDowell
11:30 a.m. Workshop: Crisis Communication with Thom Fladung
12:30 p.m. Lunch (taco bar, dessert, and beverages)
1:30 p.m. Workshop: Crisis Communication with Thom Fladung
3 p.m. Wrap-up
3:30 p.m. (optional) Experiential tour of SJCPL
St. Joseph County Public Library is planning a unique tour experience for in-person attendees!
Learn more about the resources, services, and spaces that SJCPL’s Main Library has to offer on a staff led tour. Highlights will include:
- The Youth Services Department
- The library’s new bookmobile, The Dream Machine
- Studio 304
- A hands-on learning activity in the Local & Family History Department
- Crisis Intervention staff, including the library’s in-house social worker, will also be available to discuss how SJCPL has moved to a trauma informed approach when interacting with patrons.
Note: tour times will be determined based on feedback from the event registration form.
Kate McDowell, author and professor at the School of Information Sciences at the University of Illinois at Urbana Champaign will present on data storytelling in libraries.
About Kate McDowell
Professor Kate McDowell focuses on storytelling as information research, social justice storytelling, and how the history of library storytelling can enhance contemporary data storytelling. Her projects engage contexts such as public libraries, non-profit fundraising, and health misinformation in online discourse. This research takes many forms, from publications to storytelling workshops and toolkits to research roles with international coalitions and working groups. She leads the nationally-funded Data Storytelling Toolkit for Librarians project to equip libraries with narrative tools for data-informed advocacy, which has been used by over 5,000 librarians in over 50 countries so far. Her book for libraries, Critical Data Storytelling for Libraries: Crafting Ethical Narratives for Advocacy and Impact, came out in 2025.
Read more about Kate McDowell on her website.
Thom Fladung will lead a hands-on workshop on crisis communication best practices and techniques including brainstorming key messages and participating in mock interviews, to help you prepare for any media interview or public speaking opportunity. With his practical approach to instruction and years of experience, you will walk away with pragmatic tips and best practices that you can put into play immediately to effectively communicate during a crisis.
About Thom Fladung
Thom Fladung serves as managing partner for Hennes Communications. He brings more than 33 years of daily newspaper and digital media experience to the agency, having served as a top editor at some of the nation’s largest newspapers such as the Cleveland Plain Dealer and the Detroit Free Press. Over the past decade, Fladung has also played a lead role in helping newsrooms enter the digital age, including web, social media and handheld digital devices.
Thom is an expert at crafting effective, strategic messages on hard deadlines. He is also experienced at quickly evaluating, assembling and disseminating information – crisis management skills that are critically important for clients coping with reputation management issues and breaking crises. In 2017, Thom received the Communicator of the Year award from the International Association of Business Communicators.
Learn more about Thom on the Hennes Communications website.
Special thanks to our location sponsor
As usual, it’s a very busy time at MCLS as we close one fiscal year (FY) and begin another. Here are some updates about what’s happening as we move from FY2026 to FY2027.
Midwest Collaborative for Library Services exists so that:
Libraries can benefit by gaining expanded access to resources, innovative and stable library services, and collaborative efforts, worth the continuing investment of members and affiliates.
Our Board used data from their 2025 survey of MCLS members to create this statement, the first major revision to the Board’s vision for MCLS since November 2017. The staff and I have already begun operationalizing elements of it as part of implementing the current MCLS strategic plan and we’ll have much more to say about that in future MCLS newsletters.
Our dedicated staff are hard at work on a variety of other projects including considering new vendors and products for our eLicensing program, adding new training members have requested, continuing to improve our accounting and financial processes and infrastructure, preparing to launch a new MCLS website, and many more. Together, we work to help libraries, partner organizations, and community initiatives grow and thrive however possible.
How does or could MCLS help your library? Let me know at garrisons@mcls.org.
Just a reminder to all MeLCat participants that if you need help, email melcathelp@mcls.org and include your agency code in the subject line. Some examples of MeLCat questions include:
Complete the RIDES Assistance Form at mcls.org/rideshelp to report RIDES issues, such as:
Thank you all for making MeLCat and RIDES successful!
The MeL project was made possible in part by the Institute of Museum and Library Services through the Library of Michigan.
by TALK Coordinator Ann Kaskinen
Every Child Ready to Read® (ECRR) identifies five practices (talk, sing, read, write, and play) that adults should use to engage with children to build early literacy skills. While there are many ways to incorporate reading into a baby’s daily repertoire, board books are key developmental tools. In fact, board books have become so important that in 2023 the Margaret Wise Brown Board Book Award “was created to highlight the impact of high-quality board books on the learning and development of babies and toddlers.”
According to Caitlin Gallingane, clinical assistant professor at University of Florida’s College of Education, “A tot won’t get the same impact from a picture book or YouTube storytelling, because language retention increases with multisensory input: Being able to look at something, hear something, touch something, say something, all at the same time, reinforces that word and that concept more strongly.”
TALK: Text & Learn for Kindergarten, based on the ECRR model, incorporates board book suggestions into several of the two, age-appropriate texts sent to parents and caregivers each week. Texts are sent with the goal of raising the frequency and quality of parent/child interactions, and engaging young children with board books is just one of the many ways to help prepare them for kindergarten.
If your library would like to find out how TALK can help support early literacy development in your community, send queries to talkhelp@mcls.org.
Request a quote here.
References
Cornwall, Gail. “Solid Stories: Why board books are key developmental tools.” School Library Journal, vol. 69, no. 10, Oct. 2023, pp. 38–41.
by MCLS Engagement Strategist Laura Warren-Gross
The collaborative work of public libraries is always amazing. I recently visited Karl Stutzman, the director of Milford Public Library in Indiana. When I walked into the beautifully maintained Carnegie Library, I was immediately drawn to a series of displays.
Karl explained that Kosciusko County is hosting a passport tour in honor of America 250. As a part of the tour, Maureen, the Associate Director of the library, curated more than a dozen displays illustrative of the history of the town and the library. Items include photographs of the town and library, furniture from the original Carnegie Library, a card catalog and other library-related objects, sports memorabilia, and even an autobiography of Dorthea Kerlin, Milford Public Library’s longest-serving director. These displays demonstrate the library’s prominent place though many years of Milford’s history.
Being a part of a countywide event draws folks into the community who might not otherwise visit Milford Public Library. While there, visitors can also enjoy the beautiful gardens that surround the building. They were designed and donated by a landscape architect who grew up in Milford and maintained by his local extended family—another collaborative project that benefits the library and beautifies the town.
What makes your library unique? What types of projects are you working on at your library? Engagement, Consulting, and Training team members would love to hear about your library and share your story! Interested? Contact us at engagement@mcls.org.
Recently, MCLS worked with EveryLibrary Institute and a team of students from the University of Michigan-Ann Arbor School of Information (UMSI) on a research project about the positive impact libraries make for each citizen on their lifelong learning and literacy journey. The project originated from summer 2025 discussions about how library associations and organizations could support Indiana and Michigan libraries collaboratively in a time of major disruptions and threats to library funding. Given different needs in each state, MCLS partnered on the project I describe below to focus on Michigan, and on a separate project focused on Indiana that is currently underway.
I thank Lisa Waskin (MCLS Board of Directors, Superior District Library), John Chrastka (EveryLibrary Institute), Lori Donovan, Kristin Fontichiaro, and Anthea Josias (UMSI) for their work to conceive and support our project. Most importantly, I thank our UMSI SI699 student team, Madeline Brookman, Ellie Franklin, and Sofia Frumkin, for all their work on the research and documents they produced (including an annotated bibiography, a course paper, a white paper, and a poster they presented at the UMSI Student Project Exposition on April 20).
Following summer 2025 meetings between library association leaders, John, and myself, a group of Michigan library leaders and EveryLibrary Institute agreed on a need for data that can support other work to help libraries demonstrate their positive impact (such as developing policy briefs and other information). Through other conversations in fall 2025, UMSI approached our group about proposing a student research project for their SI699 Mastery Course, and we agreed to submit. Lisa drafted a project proposal in consultation with John and me. By early January, UMSI had accepted our proposal and it had been selected by our student team. John, Madeline, Ellie, Sofia, and I began meeting as a project team, and John created a work plan to guide the students’ work framed around the following elements:
Our project team agreed that the main project deliverables would be an annotated bibliography and an SI699 course paper. The students also decided to create a short white paper summarizing their findings and conclusions with references (in addition to a poster for the exposition).
As their semester ramped up, our student team began an iterative approach to search the literature and find data from various Michigan state agencies and organizations, national resources, and foundations, with advice from John, help from UM-Ann Arbor Education Liaison Librarian Karen Downing and retired school librarian Kathy Lester, and frequent communication with each other. They also found a February announcement about literacy investments in Michigan Governor Gretchen Whitmer’s proposed FY2027 budget, which does not mention funding for libraries.
Some of the student team’s key data findings were as follows (see references list below):
In the course of their research, our student team came to recognize how vital libraries are for people’s development and success in their communities. Their course paper conclusion noted that:
When libraries are well funded, their patrons are able to access countless resources, participate in civic engagement, and grow academically and socially. School libraries, public libraries, and university libraries…are all integral to the improvement of literacy rates… When libraries have increased numbers of qualified staff, larger collections, more resources, and are open for more hours, users are consequently more successful academically… Furthermore, library programs can be used for more specific scenarios for Michigan residents, including building up financial literacy and independence, as well as opportunities for learning and advancement for incarcerated populations (Brookman, Franklin, & Frumkin, SI699 course paper pp. 11-12).
The students recommend strongly that Michigan provide more funding for libraries and see a significant opportunity given Governor Whitmer’s literacy priority. They also offered other advice to MCLS and EveryLibrary Institute, including looking beyond literacy in future work about the library’s benefits, monitoring political trends in Michigan and other midwestern states, and conducting primary research with library users.
Moving forward from this great opportunity to work with enthusiastic and energetic students and EveryLibrary Institute, MCLS will continue pursuing opportunities to gather and share information about the positive impacts that libraries make for people across all stages of life. If you would be interested in learning more or getting involved, please let me know. We are interested in doing a similar project focusing on Indiana.
I am always open to hearing ideas for how MCLS can support libraries. I hope to hear from you soon at garrisons@mcls.org.
References
The MCLS Board of Directors Nominating Committee seeks nominations from the MCLS membership for the following Board openings for 2027-2029:
Each seat serves a three-year term, beginning Jan. 1, 2027, and expiring Dec. 31, 2029.
The Board meets four times per year: in February (via Zoom), and in May, August, and November (in person), alternating between Indiana and Michigan. The November meeting includes a Board orientation and a two-day strategy retreat to review activity of the previous year, assess trends, and determine strategic changes to MCLS’s services and offerings. Newly-elected Board members are asked to attend this year’s annual retreat, Oct. 25-27, 2026. MCLS reimburses Board members for all direct meeting expenses.
The MCLS Board follows the Policy Governance Model developed by John and Miriam Carver. New Board members will receive an orientation to Policy Governance the day prior to the Board retreat (Oct. 25).
MCLS’s members are also its owners. The Board represents your interests as owners. Through the nominating process, you have the opportunity to put forth the names of those who will define our Ends and Limits, both of which guide MCLS staff as they consider the products, programs, and services MCLS offers. The slate of candidates will be chosen from the nominations, voted on by the current Board of Directors in August, and presented to membership for election in early September. MCLS will announce Board election results in October.
To assist you in nominating candidates, please read Section 3 of the Board Policy Manual for an overview of the Board’s work and responsibilities. Under MCLS’s Bylaws Section 4.03, only designated Member Representatives or Alternates from MCLS member institutions are eligible to serve on the Board.
If you are interested in serving on the Board of Directors or wish to submit a nominee, please complete this form. The deadline for submission is 5 p.m. Eastern (4 p.m. Central) on Wednesday, July 1, 2026. If you would prefer to mail your nomination, please send it to: MCLS Nominating Committee, 1407 Rensen Street, Lansing, MI 48910-3657.
MCLS is currently preparing for an exciting new member year beginning July 1! The key contacts (directors, billing contacts, and primary contacts) will receive a membership renewal email in early June (schools received their renewal emails in May).
This email includes information about the benefits you’ve accessed so far in the current member year, how we’ve succeeded together as an MCLS community, what we will do together in the coming year (including a new members-only event), and how to update your key contacts. Renewal invoices will arrive in a separate email.
If any of your key contacts have changed or you have questions about membership, please contact Gwen Haviland at membership@mcls.org or 517-939-1388.
If you are not yet an MCLS member and want to learn more, visit our membership page.
Recent studies suggest that feelings of loneliness and isolation are on the rise. Can libraries combat this trend?
Join our July Virtual Dialogue “Combatting Loneliness and Isolation” on Thursday, July 16, 10:30 a.m. to noon Eastern (9:30-11 a.m. Central) to get fresh ideas and share how your library is working to bring people together.
Our Virtual Dialogues are designed to provide those in the library industry opportunities to connect around topics that impact the way we work. They are not workshops or webinars, but rather a way to engage with others in the profession through facilitated dialogue. Please plan to have your microphone enabled and camera on to participate.
If you have questions, please reach out to engagement@mcls.org. We look forward to connecting with you!
by MCLS Engagement Strategist Laura Warren-Gross
I recently visited with Cindy Casper who serves as both the director at Eau Claire District Library and the interim director at Sodus Township Library in Michigan. She graciously shared what makes these libraries special.
Located only six miles apart, the libraries have operated separately until recently. Cindy, along with the Friends of the Library and the Boards of both libraries, has been working to merge the libraries into one entity.
Cindy has written grants to expand programming for both libraries. One example is a series called Back to the Basics which teaches skills like how to make cheese and butter, raise chickens, and sew. There is also a program called Cook the Books which brings patrons together to share recipes they have made from a common cookbook. These programs resonate with me because the library is offering members of both communities opportunities to gather, share, and learn together.
During my visit, the Friends of the Library group was holding a book sale, a 3-D printer was humming along creating dinosaurs for the summer reading kickoff party, and Cindy shared some work done by volunteers from the University of Michigan iSchool. Everything that is happening at both libraries is focused on creating welcoming, vibrant hubs for two small southwest Michigan communities.
What makes your library unique? Engagement, Consulting, and Training team members would love to hear about your library and share your story! Interested? Contact us at engagement@mcls.org.
This month, I have a simple ask: if you received a link to our MCLS member or partner/vendor survey and haven’t completed it yet, please do so before May 15. We want to hear from you about how we’re doing toward achieving our current strategic plan objectives and how we might improve.
Not sure if you got a link? Please check your junk folder for a message dated April 14 from the Indiana University Center for Survey Research (member survey) or from MCLS (partner/vendor survey), or a follow-up reminder.
In many cases, MCLS serves or works with multiple people in one library or organization – we want to hear from everyone who received a survey link! Our 10–15-minute survey includes rating and open-ended questions, and we hope you’ll take the time to answer as many questions as possible.
Together, we will continue navigating MCLS toward making a positive impact on the library community. Questions? Contact me at garrisons@mcls.org. In the meantime, thank you again for providing us with your very important input!
MCLS is currently preparing for an exciting member year, which begins July 1, 2026!
The key contacts (directors, billing contacts, and primary contacts) at school libraries will receive a membership renewal email in early May. All other libraries will receive their renewal email in early June.
This email includes information about the benefits you’ve accessed so far in the current member year, how we’ve succeeded together as an MCLS community, what we will do together in the coming year (plus a save the date for a new members-only event), and how to update your key contacts. Renewal invoices will be sent to billing contacts in a separate email.
If any of your key contacts have changed or you have questions about membership, please contact Gwen Haviland at membership@mcls.org or 517-939-1388.
Please join us in welcoming Westville-New Durham Township Public Library (IN) to our member community!
MCLS membership is exclusive to Indiana and Michigan libraries of any type and size. Learn more about the benefits of joining MCLS, a strong community of 600+ libraries; then, fill out our online application or contact Gwen Haviland at membership@mcls.org or 517-939-1388 for assistance.
Free Virtual Event | Thursday, May 14 | 10:30 a.m. Eastern (9:30 a.m. Central)
Registration is open for our next Virtual Dialogue on Thursday, May 14, from 10:30 a.m.-noon Eastern (9:30-11 a.m. Central)! This month we’ll discuss “How to talk about the elephant in the room.”
Our Virtual Dialogues are not courses or webinars; they are designed to provide opportunities for those in Indiana and Michigan libraries to connect and engage around various topics relevant to library staff. After setting up the topic, groups will discuss how they approach difficult but important conversations, particularly when they might be contentious. Please plan to have your microphone enabled and camera on to participate and learn from each other’s experience.
MCLS has spent the last several months working with library staff to get them up and running on MeLCat. We are pleased to announce that the following new libraries went live on MeLCat:
Leanna Hicks Public Library of Inkster also rejoined MeLCat after a couple of years off.
Is your library interested in joining MeLCat? Applications to join are always welcome, and you can find more information here.
The MeL project was made possible in part by the Institute of Museum and Library Services through the Library of Michigan.
Every Child Ready to Read® (ECRR) identifies five practices (talk, sing, read, write, and play) that adults should use to engage with children to build early literacy skills. Through singing, children can practice the rhythms and rhymes of spoken language, learn new vocabulary words and their meaning, learn about story structure, and develop memory skills. Additionally, “Learning about the rhythms, pitches, and steady beat within music transfers well to literacy skills like phonological awareness” (Hooper, 2023).
TALK: Text and Learn for Kindergarten, based on the ECRR model, sends 2 texts per week to parents and caregivers that suggest age-appropriate activities that build early learning skills, with the goal of raising the frequency and quality of parent/child interactions. Many of these texts not only encourage singing with children, but they also offer links to lyrics as well as images and video clips to show the accompanying movements. To access song lyrics and sing-and-move songs included in the TALK texts, go to https://textandlearn.org/tools/songs/.
References
Hooper, A. (2023). Sing and Play Your Way to Reading: Building Emergent Literacy Skills in Infants and Toddlers through Music. Reading Teacher, 76(4), 451–458.
MCLS partners with more than 70 vendors and publishers to provide member libraries with discounted pricing and centrally negotiated licensing. We regularly review expressions of interest from prospective vendor partners and add an average of four new vendors per year.
How do we identify prospective partners?
Vendors regularly reach out to us, promoting their products and services. We also engage with potential vendor partners at conferences and other events, which helps us build awareness of emerging products and acquisition models in the eLicensing landscape.
How do we decide which vendors to work with?
When we receive solicitations from vendors, our eLicensing & Collection Resources team does an initial review, looking for purveyors who offer the types of products requested by our member libraries. If we determine there may be interest, we request that the vendor submit an expression of interest, which helps us understand more about how they work with library consortia and whether they may be a good match for MCLS members.
You can inform our vendor decisions!
Our member libraries’ input is the most important factor in whether we pursue an agreement with a vendor or publisher. There are several ways you can contribute to these decisions, on an ongoing basis:
Periodically, we send updates or requests for input to member libraries about potential partnerships we’re exploring. Here are just some of the potential partners we’re looking at:
FREE Virtual Events | June 1, 3, 5, 2026
Join the Linked Data Users Group of the Midwest Collaborative for Library Services (MCLS) and the Program for Cooperative Cataloging’s EMCO Wikidata Community of Practice (CoP) for a free, semi-synchronous, week-long virtual event that explores Wikidata. No prior experience is necessary! Project staff will provide you with everything you need to create and edit Wikidata entities.
This edit-a-thon will take place the week of June 1st. An opening event on the 1st will include an introduction to editing Wikidata and to PCC’s EMCO Wikidata CoP. A closing event on the 5th will review and celebrate what we achieved together. A Slack channel will be available to communicate with fellow Wikidata editors throughout the week.
In this edit-a-thon, we will focus on adding corporate bodies (businesses, associations, institutions, etc.) using the PCC EMCO Wikidata CoP Application Profile for Corporate Bodies. Participants may create Wikidata entries of their own choosing or create and edit entries from a list provided by the edit-a-thon staff.
These events are free to all and will take place via Zoom; however, you must register in advance. Join for either event and edit during the week as much as you’d like. We will provide instructions, tools, data sources, and an optional Slack channel for chat
If you have questions, please contact LDUG steering committee chair Marianne Swierenga, marianne.swierenga@wmich.edu. And if you’re ready to join us, use the registration link to reserve your spot.
Before the Event
The following library staff members have earned Certificates of Library Staff Development by attending workshops through MCLS!
Basic Essential Workplace Skills Certificate (FREE*)
Pamela Wright, Rawson Memorial District Library, MI
Basic Cataloging Certificate
Jordan Ehrmann, Novi Public Library, MI
Robert Lebowitz, Bronx Community College, NY
Advanced Cataloging Certificate
Sarah Mominee, Novi Public Library, MI
For questions, please email Gwen at training@mcls.org or call 517-220-9950.
*Essential Workplace Skills tutorials are FREE for all staff at MCLS member libraries!
There are a multitude of benefits to being a member of a large collective like MCLS, which has more than 600 members of every size and type of library across Indiana and Michigan. MCLS offers affordable and customizable access to the key services and resources libraries depend on. Below is a snapshot of how we are investing in our members:
The MCLS membership year is July 1-June 30.
Last updated June 4, 2026.
As MCLS Executive Director, I lead staff who truly care about providing the best possible services and value to libraries, including through partnerships with other organizations and the many vendors we work with. The investment you make in MCLS in terms of membership and/or the time you spend working and communicating with our staff is invaluable to us as an organization. We don’t take that investment and the relationships it fosters for granted – without those things, we wouldn’t exist. I say often that “relationships are everything at MCLS,” and I really mean that. We strive to maintain relationships that are as positive and productive as possible, and part of how our current strategic plan guides us to do that is to gather input about how we’re doing and how we might improve.
Over the past few years, many in the MCLS community have provided helpful feedback about their experience working with us in a variety of ways, from consulting and other evaluations to our 2023-2024 strategic planning process and our Board’s member survey in fall 2025. This month, we are launching a new annual survey for member libraries and our partners and vendors to establish baseline data about how well we are achieving the objectives in our current strategic plan and where we can improve. We will use the survey data to inform how we make decisions and allocate resources toward achieving our objectives over time in terms of our Key Strategic Priorities of Engagement and Collaboration, Invest In Innovation (TALK libraries only for our 2026 survey), Strengthen and Support, and Awareness and Accountability.
Our survey will proceed along two tracks: one for member libraries, and another for partners and vendors.
Both surveys will close May 15, and we expect to have data compiled by the end of June to review during summer 2026.
The survey will include some rating questions as well as some open-ended questions, including several near the end that I’ll ask you to think about before you receive a link:
The survey should take about 10-15 minutes to complete, and we hope you’ll take the time to answer as many open-ended questions as possible. We value your unique perspective and encourage your honest input.
Our staff and I thank you in advance for investing the time to take our survey. Together, we will continue navigating MCLS toward making a positive impact on the library community.
If you have questions about what we’re doing and why, please contact me at garrisons@mcls.org. In the meantime, thank you again for providing us with your very important input about how MCLS is doing for libraries and our partners and vendors, and how we might improve for you.
MCLS is currently preparing for an exciting member year. The key contacts (directors, billing contacts, and primary contacts) at school libraries will receive a membership renewal email in early May. All other libraries will receive their renewal email in early June.
This email includes information about the benefits you’ve accessed so far in the current member year, how we’ve succeeded together as an MCLS community, what we will do together in the coming year (plus a save the date for a new members-only event), and how to update your key contacts. Renewal invoices will arrive in a separate email.
If any of your key contacts have changed or you have questions about membership, please contact Gwen Haviland at membership@mcls.org or 517-939-1388.
Free Virtual Event | Thursday, May 14 | 10:30 a.m. Eastern (9:30 a.m. Central)
MCLS’s popular Virtual Dialogue series continues Thursday, May 14, from 10:30 a.m.-noon Eastern (9:30-11 a.m. Central). Our Virtual Dialogues are not courses or webinars; they are designed to provide opportunities for those in Indiana and Michigan libraries to connect and engage around various topics relevant to library staff. Please plan to have your microphone enabled and camera on to participate.
We look forward to connecting with you! Register today and watch for topic announcements coming soon on email lists and our website.
If you have any questions, please reach out to engagement@mcls.org.
The following library staff members have earned Certificates of Library Staff Development by attending workshops through MCLS!?
Basic Essential Workplace Skills Certificate?
Basic Cataloging Certificate
Are you interested in obtaining your Certificate of Library Staff Development? For details, see our website. Essential Workplace Skills tutorials are free to MCLS members as a member benefit! For questions, please email Gwen at training@mcls.org or call 517-220-9950.
On March 17, 2026, Beanstack and LibraryPass (Comics Plus) announced a merger to form Joyful Reading Company. Coverage of the acquisition was published in Publishers Weekly and Library Journal.
MCLS partners with both former companies to offer discounted pricing on subscriptions, and we’re pleased to share that we will continue to work with them as Joyful Reading Company. We are in the process of making necessary updates in our systems to reflect this change and will continue to keep members informed about products and pricing in the coming months.
Spring conference and event season is just around the corner, and I encourage you to engage with MCLS staff at conferences and events that you may be attending. Have a question, idea, or story to share? I hope you’ll find us!
In March, the following MCLS staff will be at the following conferences and events:
Electronic Resources & Libraries (March 1-4)
Sarah Beaubien, eLicensing and Collection Resources Manager (presenting March 4 at 9 a.m.)
Michigan Society of Association Executives 2026 Public Policy Roundtable (March 10)
Scott Garrison, Executive Director
Sean Cwiek, Information Technology (IT) Manager
Chelsea Denault, Michigan Digital Preservation Network (MDPN) Coordinator
Scott Garrison, Executive Director
In April, we’ll hope to see you at the following conferences and events:
Public Library Association (PLA) Conference (April 1-3)
Ann Kaskinen, Text and Learn for Kindergarten (TALK) Program Coordinator
Mary Ruthko, Marketing and Communication Specialist
Michigan Library Advocacy Day (April 28)
Jan Davidson, Library Consultant
Laura Warren-Gross, Engagement Strategist
In May, we’ll hope to see you at the following conferences and events:
Michigan Academic Library Association Conference (May 7-8)
Sarah Beaubien, eLicensing and Collection Resources Manager
Kalyn Huson, Association Administrator and Administrative Specialist
Pam Seabolt, Engagement, Consulting, and Training Manager
Medical Library Association Annual Conference (May 19-22)
Susan Bannwart, eLicensing and Collection Resources Coordinator
Academic Libraries of Indiana Annual Meeting (May 11)
Scott Garrison, Executive Director
In June, we’ll hope to see you at the following conferences and events:
Michigan Archival Association Annual Conference (June 15-16)
Chelsea Denault, MDPN Coordinator
American Library Association Annual Conference (June 26-29)
Susan Bannwart, eLicensing and Collection Resources Coordinator
Sarah Beaubien, eLicensing and Collection Resources Manager
Our staff look forward to seeing you and learning along with you this spring. Again, I hope you’ll engage with us when we’re in the same place at the same time.
If there’s anything I could do for you, let me know at garrisons@mcls.org.
MCLS recently welcomed the following new libraries to our member community:
MCLS membership is exclusive to Indiana and Michigan libraries of any type and size. Learn more about the benefits of joining MCLS, a strong community of 600+ libraries, on our Membership page. Then, fill out our online application or contact Gwen Haviland at membership@mcls.org or 517-939-1388 for assistance.
Funding for early learning saw big changes in both Indiana and Michigan this past year. Indiana significantly cut its preschool (On My Way Pre-K) and childcare funding, creating fewer slots for low-income families to send their 4-year-olds to high quality preschool programs. And, while Michigan bumped up its PreK for All initiative targeting 4-year-olds, it simultaneously eliminated over $19 million in funding for Great Start Collaboratives (birth to 3-year-olds).
One of the ways libraries can support early literacy in their communities is by subscribing to TALK: Text & Learn for Kindergarten, which encourages caregivers and parents to read, write, talk, sing, and play with their little ones every day. TALK does not offer a replacement for preschool programs, but it does offer an effective way for libraries to support families amid recent changes. If your library subscribes to TALK, be sure to reach out to educational organizations that provide services to birth to 5-year-olds such as Intermediate School Districts (ISDs) and Regional Educational Service Agencies (RESAs) in Michigan, Educational Service Centers (ESCs) in Indiana, and Head Start programs in both states to let them know how easy it is to participate.
Learn more about TALK or request a quote here.
Writing a personal remembrance of Randy Riley is something I’d never expected I would do during my career. It’s difficult because his passing was sudden and is so much to process as someone who knew and worked closely with him. It’s also not difficult because of how grateful I am for him and everything he gave so many as a leader and colleague, and as a person. Through his work and in life, Randy made a profound, incalculable difference.
As many statements from organizations including the Library of Michigan (LM), Library of Michigan Foundation, Michigan Academic Library Association (MiALA), Michigan Library Association (MLA), and University of Michigan School of Information have noted, Randy was a singular and exemplary professional. Through his decades of devoted service to libraries and citizens throughout Michigan, he supported and led many important initiatives and fostered and promoted excellent access to a wide array of information. Randy’s affinity for genealogy and special collections tracked along with changing technology (e.g., in the form of LM’s support for the DPLA Michigan Service Hub, Michigan Memories, and the Michigan Digital Preservation Network [MDPN]). His strong support for MeL, the Michigan Notable Books program, LM’s grant programs, library staff professional development, and more endeared him to hundreds of libraries statewide. Randy was known as a relentless advocate who was generous with his time and help for libraries and library staff. He fielded as many questions and inquiries, visited as many libraries, and met with as many groups as he could. During the visits he and I made together, I marveled at his knowledge of what was happening at libraries of all sizes.
Randy also kept the Michigan library community connected to the wider profession through his work with the Chief Officers of State Library Agencies (COSLA) and as a member of the MCLS Board of Directors. He maintained countless long, positive, productive relationships with deep connections, including with some of us at MCLS, and called on his vast network to help the community through hard times when needed. People knew they had Randy’s support and answered his call in return whenever possible. His steady hand was invaluable through all the federal and state political and budget turmoil of 2025, and he rallied and guided many to engage and speak on behalf of MeL and other critical programs.
Randy was an articulate, incisive, thoughtful, passionate, and supportive constant presence on the MCLS Board for over ten years. As with so many other groups, it was rare that he’d miss a Board meeting. Though he would usually have plenty to say, he’d often let others in a larger group speak before weighing in on an issue. After we’d served on the Board together for a few years, Randy was one of the first people I called to seek advice about whether to apply for the Executive Director position. He urged me to go for it, and doing so changed my life. When I joined MCLS, our relationship evolved. We shifted from being fellow Board members to being the people who had the responsibility of leading the organization that made MeL possible and the organization that supported it. I came to see more facets of the complex person Randy was. I’d known him to be approachable, open, caring, direct, and funny. He also resisted anything he considered “touchy-feely,” and sometimes had an edge. He could be impatient when urgency to make a point got the better of him. I learned quickly that when he’d interrupt me mid-sentence, it was because he had an important point to make or question to ask based on his experience and thoughtful deliberation. He played such an important role that I always listened. When we were together, we would often have intense conversations on topics ranging from libraries to state and federal government to many aspects of life outside of work. He was usually much more concise in writing, often emailing a single sentence or question with the simple signature “r.”
Beyond libraries, we spoke often about our families, activities that included travel (e.g., family visits and his fishing trips), books he recommended, and our shared passion for music from many genres. Knowing Randy was nearing retirement, I asked for updates on his future plans. He’d say that he wanted to continue working while he could still “do cool things.” He wanted to guide newer LM staff including managers Michelle Bradley and David Votta. He also said that he didn’t want to end his career in bad times for libraries. He suggested that there were cycles of support for libraries and that we were either in or approaching a trough period. I appreciated how often he would urge us to stay strong and find ways to climb back up to a peak. As pained as Randy was by those who label librarians as “groomers” and “pedophiles,” he truly believed that libraries could have a bright future if librarians love and engage with people.
Randy used to joke that he had a “life sentence” on the MCLS Board until retirement (as the Indiana and Michigan state librarians each have a permanent Board seat). I knew the day would come when Randy would leave our Board, and I had not yet prepared fully for what it would mean to lose his voice, his experience, and his belief and faith in our organization through its successes, challenges, and potential. He told me during the November 2025 MCLS Board retreat that it would be his last, and I took that to mean that he was planning to retire in 2026 though he hadn’t announced anything official. I looked forward to wishing Randy the long, happy, and healthy retirement he so richly deserved.
On January 4, I learned Randy had passed the previous night. I was absolutely shocked and heartbroken.
I am heartbroken.
I am heartbroken for Randy, his wife Lori and their family and friends that he didn’t get to enjoy retirement with them. I am heartbroken for the LM staff, the Michigan Department of Education (MDE), and the greater library community having lost him so abruptly.
As I started working through an enormous sense of loss, I started writing about the impact Randy had made and my memories of him. The words just flowed. Many of my MCLS colleagues and I were fortunate to join hundreds of others who mourned him at LM on January 9. The memorial was as singular as Randy was. The heartfelt comments from many of Randy’s colleagues, friends, and especially his brother Mark, will remain with all who were there.
Today, I move between gratitude and grief. I’m glad for so very many things, and sad for so many others. I’m glad Randy was able to provide such stable leadership at LM and for the many boards and working groups on which he served. I’m glad he was able to celebrate MeLCat’s 20th anniversary last year. I’m especially glad that Randy got to enjoy 37 years of marriage to Lori filled with so many rich experiences including all the time spent with their children Sam and Madeline and pets including his beloved dog Louis (pronounced like the French kings). He was clearly so proud and supportive of each member of his family, and I’ll miss hearing him talk about them. I’m glad Randy got to spend so much time traveling to fish, visit family, and see his favorite bands. I’m glad for the times I got to see bands with him, including The Baseball Project at Bell’s Back Room in Kalamazoo and The Hold Steady at Brooklyn Bowl Philadelphia. I’m sorry I never got to play him the bass solo he’d needled me about for years, at a Lighting Matches show. I’m grateful for the time he gave me for our monthly breakfast meetings and so many other conversations. I’ll miss wondering what discussion topics were on his list and whether I was as ready as he was to dig deeply into them that day, which eyeglasses he’d be wearing, whether or not he’d have a beard, what book and music recommendations he’d offer, and looking for his truck in the parking lot to remind me how late I was for our meeting (he was remarkably patient about that). I’ll miss his simple parting words: “Talk to you.”
Randy Riley was one of the kindest, most generous and supportive colleagues I’ve ever had. Whether he’d say so or not, he truly cared deeply about many, many people in his life. It was just obvious. While he spoke so many meaningful words so easily at library events across the state and in meetings around the country, his actions spoke much louder.
I am one of the innumerable people for whom Randy made an immense positive difference. I am thankful for his work, contributions, vision, insight, experience, humor, and everything else he shared with us. I will honor his memory by striving to be the forthright and decisive leader he pushed me to be. I’ll do what I can to help the library community stay strong, pull together, and collaborate, as he urged. I’ll read more, including the Michigan authors he championed. I’ll seek out and stay open to new music and invite others to join me to see bands more frequently.
I’m glad Randy Riley was my colleague. Working with him made my professional life richer.
I’m glad Randy Riley was my friend. Knowing him made my personal life richer.
I’m taking peace and comfort from years of great memories of Randy. If you knew him, I hope you are also.
If there is anything I can do for you, please let me know at garrisons@mcls.org.
The following library staff members earned Certificates of Library Staff Development by attending workshops through MCLS:
Basic Essential Workplace Skills Certificate
Basic Cataloging Certificate
Advanced Cataloging Certificate
Are you interested in obtaining your Certificate of Library Staff Development? Any staff member at our member libraries can take Essential Workplace Skills tutorials for FREE! Learn more about library staff development certificates on our web page.
If you have questions, please email Gwen at training@mcls.org or call 517-220-9950.
Join us at 11 a.m. Eastern (10 a.m. Central) on Wednesday, March 11, 2026, for a webinar presented by The Social History Archive.
The Social History Archive offers the most comprehensive online archive of British, Irish, and former Empire historical resources for academic research and teaching. The continually growing collection contains hundreds of millions of images of historical records and newspapers, supporting a broad range of scholarly interests. This includes:
After registering, you will receive a confirmation email with information about joining the meeting. The webinar will be recorded.
Thank you to everyone who attended the MeLCat 20th Anniversary celebrations, either virtually or in person. We’re also grateful to everyone who participated in the anniversary activities throughout this year, whether by sharing your MeLCat stories or hosting Mittens at your library. It’s always fun to connect to share our stories and libraries.
And an even bigger thank you to all the library staff, past and present, who work every day making MeLCat successful throughout Michigan.
The following library staff members earned Certificates of Library Staff Development by attending workshops through MCLS:
Basic Essential Workplace Skills Certificate
Are you interested in obtaining your Certificate of Library Staff Development? Any staff member at our member libraries can take Essential Workplace Skills tutorials for FREE! Learn more about library staff development certificates on our website. If you have questions, please email Gwen at training@mcls.org or call 517-220-9950.
Please submit a RIDES Assistance form if your library will be closed on a scheduled day of service. Short closures should be reported no more than two weeks prior to closing. Extended closures of more than 30 days should be submitted at least two weeks prior to closing.
It is not necessary to report if your library is closed on a RIDES holiday as there is no service on those days; however, please fill out the RIDES Assistance form as soon as possible if your library will be closed due to weather on your scheduled day of service.
Upcoming RIDES holidays are:
Thursday, Dec. 25
Thursday, Jan. 1
Need help? Fill out the RIDES Assistance Form.
Join MCLS this winter and spring for our popular Supervisor Series workshops, including our new Super Manager session in April! These engaging, interactive workshops include group activities, individual reflection, discussions, and hands-on practice on a variety of important skills for today’s library leaders. All Supervisor Series workshops are held on Zoom and facilitated by MCLS Library Strategist Jenny Kobiela-Mondor.
Each workshop session is worth 4 contact hours for professional development and is eligible for LEUs for Indiana public library staff, SCECHs for Michigan school library staff, and PGPs for Indiana school library staff. Contact Gwen at training@mcls.org or call 517-220-9950 to learn more.
Motivating Employees to Be Their Best
Thursday, Jan. 29, 10 a.m. – 3 p.m. Eastern (9 a.m. – 2 p.m. Central)
Discover how to tailor your leadership and communication style to better suit the needs of your employees. As a result, you will have the tools to create a shared vision for your organization or team, build group identity, create a culture of ownership, and establish a more collaborative, inspiring work environment.
Learning to Manage for New Managers
Thursday, Feb. 26, 10 a.m. – 3 p.m. Eastern (9 a.m. – 2 p.m. Central).
Minimize your stress and walk through the process of management by targeting five specific areas. You’ll learn to successfully handle staff, projects, performance, conflict, and yourself as you evaluate and continuously improve your effectiveness as a manager.
Effective Communication Strategies for Managers
Thursday, March 26, 10 a.m. – 3 p.m. Eastern (9 a.m. – 2 p.m. Central)
Learn how to be more relatable, respectable, dependable, and communicative. As a result, you will be able to have a clear direction, meet your employees’ needs, handle difficult conversations with ease, and boost your assertiveness as a boss.
(NEW!) Super Manager
Thursday, April 23, 10 a.m. – 3 p.m. Eastern (9 a.m. – 2 p.m. Central)
A Super Manager helps keep staff engaged, happy, and on board with the library’s mission. This workshop is designed to help you build Super Manager skills as you explore being consistent and flexible, displaying humility and confidence, and helping employees maintain focus in a fun working environment.
TALK: Text and Learn for Kindergarten is a text-based service for libraries that promotes the practice of talking, singing, reading, writing, and playing with children to foster early learning skills. To help patrons navigate to the TALK website and sign up for participation, please check out the TALK Toolkit, located in the For Libraries dropdown menu.
The TALK Toolkit provides all types of materials to support the promotion of TALK to your patrons. There are written examples for building partnerships with businesses, educators, and medical professionals, as well as government, faith-based, nonprofit, and civic organizations. Additionally, there is a brand kit with a variety of logos, icons, and QR codes that can be used to build a TALK presence on your library’s website.
For more information about TALK, please visit https://textandlearn.org/for-libraries/
Not currently a TALK subscriber? Request a quote at https://textandlearn.org/quote/
MCLS kicks off a new year of Virtual Dialogues on Thursday, Jan. 22 from 10:30 a.m. to noon Eastern (9:30-11 a.m. Central). We will discuss how we’ve survived and thrived amid uncertainty, and how we can use our strengths and the lessons we’ve learned to continue to serve our communities during unpredictable times.
MCLS Virtual Dialogues are designed to provide those in the library industry opportunities to connect and engage around topics that impact the way we work. These dialogues are not workshops or webinars, but a way to engage with others in the profession through facilitated dialogue. Please plan to have your microphone enabled and camera on in order to participate.
Registration is open now!
If you have any questions, please reach out to engagement@mcls.org.
We look forward to connecting with you in the new year!
Things remain busy at MCLS in this time of transitions, and I hope to see many members at the MCLS Annual Meeting on Dec. 2, 2025 at 10 a.m. Eastern (9 a.m. Central) on Zoom (please register here) where topics will include revised MCLS Bylaws and our Board of Directors’ next steps following their September member survey and recent retreat.
Following a Board vote on Nov.14 to revise the MCLS Bylaws, the MCLS members must vote to approve the revised version per Bylaws Article XI. Provided we have a quorum of 10% of MCLS members present at the Dec. 2 Annual Meeting (see Article VII Section 7.05), we will hold a vote. My Annual Meeting invitation email to MCLS members included links to the current and revised Bylaws. The 2025 Board officers (see Article V) led the Bylaws revision in consultation with MCLS’s attorney.
The main difference in the revised Bylaws is in Article IV Section 4.01 (Board of Directors Composition). MCLS would move from:
These changes mean that:
Turning to the Board’s member survey results and their next steps toward updating their collective vision and direction for MCLS (also known as Ends, on p. 3 of the Board Policy Manual), 232 individuals responded to the survey, offering nearly 700 comments in addition to answering all or nearly all of the survey’s five questions.
Here is a summary of some of the survey data:
At their Nov. 14-15 retreat, the Board considered the survey data in a broader context of driving forces that may shape MCLS’s future. After some intensive group work and discussion looking at Ends development through multiple lenses, the Board created a draft Ends document. Now under revision ahead of a Board vote in early 2026, the current version points to expanding access to resources, innovation and stability, and collaboration. I hope you’ll join us at the Annual Meeting on Dec. 2 to learn more, engage, and ask questions.
In the meantime, and as we wind through and past the 2025 holiday season and into 2026, I want to take a moment to express gratitude for MCLS’s members, partners, vendors, and other stakeholders. I thank our staff, who work hard to provide the best service we can. I also thank our Board and its officers for all the work they did in 2025 on a number of fronts and look forward to how they continue what they started this fall and help fuel MCLS’s and our community’s future. Special thanks to Indiana Academic Library Representative Josh Petrusa for his help with this newsletter piece.
I will also take just a moment here to recognize Janet LaCross, who retires from MCLS in December after a remarkable 39-year career with us. Janet has seen and helped guide MCLS through an astonishing amount of change in her many years with us, and we wish her a long, happy, and healthy retirement. We will miss Janet greatly.
I hope our December-January newsletter reaches you around a restful holiday season spent with those who mean the most to you. As always, I hope to hear from you at garrisons@mcls.org, and as we reflect on what at times has felt like a chaotic 2025, may we all have a productive and successful 2026.
MCLS recently welcomed Kirklin Public Library (IN) and Linden Carnegie Public Library (IN) to our member community!
MCLS membership is exclusive to Indiana and Michigan libraries of any type and size. Learn more about the benefits of joining MCLS, a strong community of 600+ libraries, on our website. Then, fill out our online application or contact Gwen Haviland at membership@mcls.org or 517-939-1388 for assistance.
In partnership with several publishers and EBSCO, MCLS has begun using a new agent module in ConsortiaManager. This module relates only to journal agreements that offer EBSCO billing as an option, which include Cambridge University Press, Oxford University Press, Sage, Springer Nature, and Wiley. We are rolling out use of the agent module in a phased approach starting with the Cambridge University Press Open Access Agreement. A user guide with instructions is sent with the renewal notice.
What’s different for libraries? Utilizing this module will improve visibility of pricing and workflows for members who wish to use EBSCO Billing. You will see the option to select EBSCO as a billing agent in applicable agreements. When you select this option, MCLS will invoice your library for our administrative fee, and EBSCO will invoice you for the cost of the journal package. MCLS still negotiates the license and manages the renewals. EBSCO provides invoicing services and offers libraries the following benefits:
If you have questions about the agent module, contact services@mcls.org.
Our staff have had a busy conference season, and we look forward to seeing our Indiana library community at our last scheduled stop! If you are attending the Indiana Library Federation Annual Conference from Nov. 9-11, drop by booth #15 to play our popular prize drop game and win a fun gift, grab some freebies, and chat with us. Be sure to add these MCLS presentations to your schedule, too:
This month I thank the 232 people who responded to the MCLS Board of Directors’ survey in September, and will share next steps the Board will take. The Board and I really appreciate the data MCLS members took the time to submit, including hundreds of comments.
As I mentioned in September, MCLS’s member libraries own MCLS as an organization. According to MCLS’s governance system, the Board serves as the informed voice and agent of MCLS’s owners and is accountable to the member/owners. They will use the survey data to update their collective vision and overall direction for MCLS, which the staff and I will operationalize in alignment with the strategic plan that we created in 2024 (with a great deal of input from member libraries and other stakeholders).
The Board will consider the survey data as they focus on updating their vision and direction for MCLS (also known as Ends, on p.3 of the Board Policy Manual) at their Nov. 14-15 retreat. We will share a data summary and any changes the Board made to their Ends in the December-January MCLS newsletter (watch this space). We will also offer an opportunity for MCLS members to engage with the Board on how they’re using the survey data at the MCLS Annual Meeting on Tuesday, Dec. 2 at 10 a.m. Eastern (9 a.m. Central) (registration information coming soon).
In other news, the Board will also discuss updates to the MCLS Bylaws at their meeting on Friday, Nov. 14. Once the Board approves new Bylaws, MCLS members will vote to approve them according to the methods in the Bylaws document. We’ll communicate the voting process to members well in advance of the vote.
I’ll close by noting that this newsletter finds many of us in the middle of the fall conference season. I appreciated seeing many MCLS members at the Upper Peninsula Region of Library Cooperation (UPRLC) conference in September and the Michigan Library Association (MLA) conference in October. I hope to see some of you at the Charleston Conference in early November and the Indiana Library Federation (ILF) conference the following week. I also encourage you to join us for the Annual Meeting to engage with us and learn how your member input is influencing the Board’s vision and direction work.
I appreciate how the Board is working at their level and the staff at theirs so MCLS can continue serving libraries as effectively and impactfully as possible. If you also appreciate what our Board and staff do, I encourage you to let them know.
What’s on your mind right now? Let me know at garrisons@mcls.org.
We are pleased to announce that Cromaine District Library (MI) selected Midwest Collaborative for Library Services (MCLS) to facilitate a staff day in October, and Briggs District Library (MI) has invited MCLS to provide a staff day training this winter. We are excited to work with both groups!
Are you looking for library-specific consultants, presenters, or facilitators? MCLS can help! Visit our webpage to read more or contact us to request a quote.
The following library staff members have earned Certificates of Library Staff Development by attending workshops through MCLS:
Basic Cataloging Certificate
Basic Essential Workplace Skills Certificate
Are you interested in obtaining your Certificate of Library Staff Development? For details, see our website. If you have questions, please email Gwen at training@mcls.org or call 517-220-9950. Essential Workplace Skills tutorials are free to MCLS members as a member benefit!
MeLCat is 20! To mark this amazing anniversary, we invite you to join us in person or online to celebrate.
At the MLA conference reception, registered conference attendees can find MeL team staff from the Library of Michigan and MCLS in the Lake Erie Room on the 2nd floor. Stop by to say hello, win prizes, record your MeLCat stories, and take a selfie with a life-sized “Mittens,” the MeLCat Mascot. You can also taste “Mitten’s Harvest Potion,” the MeLCat signature cocktail/mocktail, brought to us by American Fifth Distillery, and pair it with a MeLCat cookie. The MLA conference reception will take place at the Library of Michigan on Thursday, Oct. 30, from 6-9 p.m. Eastern.
For those unable to attend MLA, there will also be a virtual event in November. Join us to share MeLCat stories, follow the travels of Mittens throughout the state, and spin the virtual wheel for MeLCat prizes. Stay tuned for more details on the virtual celebration.
The MeL project was made possible in part by the Institute of Museum and Library Services through the Library of Michigan.
Several MCLS staff members will present the following topics at conferences this month. In addition, if you’re attending MLA or ILF, stop by our booth to say, “Hi!” We’ll have our popular prize drop game for you to have a bit of fun plus lots of great information, prizes, and giveaways!
National Digital Stewardship Alliance Digital Preservation 2025 Conference
October 9-10, Online
Michigan Museums Association Annual Conference
October 13-15 in Lansing
Michigan Library Association Annual Conference
October 29-31 at the Lansing Center
Indiana Library Federation Annual Conference
November 9-11 at the Crowne Plaza Downtown Union Station, Indianapolis
We are pleased to share that two valued MCLS team members have stepped into new roles as of Oct. 1, 2025!
Ann Kaskinen, former MeL Engagement Specialist, K-12, is now our new TALK Program Coordinator and Laura Warren-Gross, former MeL Engagement Specialist, Public, is stepping into the role of Engagement Strategist. Due to federal funding uncertainties, the Library of Michigan made the decision not to renew its contract with MCLS for MeL eResources training. Fortunately, MCLS was preparing to expand our team in 2025, and the timing aligned perfectly to have Ann and Laura step into these new roles.
Ann and Laura are well known to many Michigan libraries through MeL eResources training/engagement and conference presentations. In their new roles, they’ll continue to support libraries—now across Indiana, Michigan, and beyond—with even broader reach and deeper engagement.
Read on to learn more about Ann and Laura and how they’ll continue to make a difference in the library community through MCLS.
Ann Kaskinen, TALK Program Coordinator
“I am excited to begin working as the new TALK Program Coordinator for MCLS, where I can support libraries focused on improving literacy for their youngest learners. I am already starting to meet many people who are passionate about connecting community organizations and families with literacy resources for 0- to 6-year-olds.”
Ann began her career teaching high school ELA, social studies, and public speaking. After earning a library degree from CMU, she worked for 15 years as a K-12 Library-Media Specialist before joining the MCLS staff in 2019 as the Michigan eLibrary (MeL) Engagement Specialist for K-12. Ann also has experience as an ISD consultant, a teen librarian for a public library, and a government docs intern.
In her new role, Ann is responsible for Text and Learn for Kindergarten (TALK), a service of MCLS designed for public library implementation. She coordinates demonstrations, contracts, support, TALK marketing and outreach, user community-building, and future development and strategy. As a member of the eLicensing and Collection Resources team, Ann also assists the department in providing customer service for other subscriptions through MCLS. To learn more about TALK and request a quote or demonstration, visit textandlearn.org.
Laura Warren-Gross, Engagement Strategist
“I’m looking forward to building relationships with library staff in Indiana and Michigan as we continue to engage with libraries of all types.”
Laura earned a Bachelor of Science in Education and a Master of Arts in Library Media from Central Michigan University. She spent four years teaching high school English and Earth Science and 21 years as a school librarian prior to joining MCLS in 2021 as the MeL Engagement Specialist for Public Libraries. Laura participated in ALA’s Emerging Leaders program and was awarded MASL’s School Librarian/Teacher Collaboration Award.
As the new MCLS Engagement Strategist, Laura helps lead efforts to build meaningful, lasting relationships with people at all levels within the library profession. She utilizes engagement tools that combine strategic thinking with hands-on efforts to help academic, public, school, and special libraries achieve the extraordinary. If you are attending either the MLA or ILF annual conferences this fall, stop by our booth to meet her!
The MeL project was made possible in part by the Institute of Museum and Library Services through the Library of Michigan.
The MCLS management team has created a new MCLS Staff AI Use Policy that we will begin implementing in October, and I’m sharing information about it so our community is aware and can ask questions.
We know AI comes with many questions (as studies from Pew Research Center, Gallup, and others have found) and it’s very important to us that we use AI in ways that foster trust and positive working relationships with libraries and our partners. MCLS is approaching using AI very intentionally and according to our guiding principles and documents (including our core values, strategic plan, and Board and internal policy).
I’m using some questions I might expect libraries and our partners to have about how MCLS will use AI to frame this newsletter piece. I encourage you to contact me anytime with questions about AI (or anything else) at garrisons@mcls.org.
Why did MCLS create an MCLS Staff AI Use Policy?
There are many reasons. First and foremost, as some MCLS staff have begun experimenting with using AI to search for, analyze, and brainstorm or draft information, we want staff interested in using AI to have clear expectations and guidelines so they do so ethically based on our core values and policies, and in ways that keep our internal data about libraries and our many partners safe from inappropriate exposure. Our relationships with libraries and partners are very important to us, and we do not want to use AI in any way that harms relationships or trust in us as an organization.
Second, AI functionality is popping up everywhere in software that libraries and MCLS use every day. We will use our policy as a framework to help us build ways to decide what AI competencies we expect our staff to have, how we’ll provide training, and which AI functionality we’ll allow staff to use in which software.
Third, library vendors have begun incorporating AI functionality into their products and including language about AI in their licenses. The more we understand AI and its implications, the better we can support libraries.
How did MCLS create its AI policy?
We started by looking at other library consortia and libraries’ AI policies and asking AI to suggest policy elements we should consider including. One policy that was particularly helpful was the Kenosha Public Library Artificial Intelligence & Machine Learning Policy. Our management team reviewed multiple policy versions before approving the version 1.0 policy we are implementing now. Because AI changes rapidly, our management team will review and update our policy at least quarterly.
How does MCLS plan to use AI?
As I noted above, we’ve already begun experimenting. If we use AI to help us create content that we make public, we will state that clearly. We will also explore how we might use AI internally to do rote tasks, data analysis, reporting and other work more easily and efficiently in ways that protect our internal data from being exposed outside closed AI that we and our software providers can control.
How will MCLS protect my library’s data from inappropriate exposure?
Our policy is very clear that staff will not expose data that libraries and their staffs have entrusted to us to any publicly accessible AI system, for training or any other purpose.
Will MCLS offer training on AI?
We have begun discussing this and will communicate about any AI training we may offer in the future.
How will MCLS deal with ethical concerns around AI including but not limited to privacy, confidentiality, accuracy, bias, and AI’s resource consumption and environmental impact?
Our policy includes a set of questions staff must ask before using AI, including how AI stores data and who has access, how we might mitigate any bias AI has based on its training data, and how we’ll verify that what AI generates is accurate. It also has sections on data privacy and confidentiality, and we state clear expectations including that staff must not use AI to generate content that is unethical, offensive, or in violation of MCLS policy. While we see great potential to gain efficiency through AI, we are conflicted about the fact that AI consumes a great deal of computing power, water required to cool servers, and other resources. We also have concerns over regulations (or the lack thereof) regarding AI in our current volatile times.
Will you share your MCLS Staff AI Use Policy?
No, not at this time. We are in the process of implementing the policy with our staff and have more work to do to ensure we have clear expectations and processes to follow. We want you to be aware that we have a policy, for the reasons outlined above. You are welcome to ask me any questions you may have about our policy, at garrisons@mcls.org or by phone at 517-489-4071.
What AI competencies does your library consider most important for staff? What AI training have you or your staff have taken that you’ve found helpful? What questions or concerns might you have about how MCLS might use AI to improve how we serve your library? What else might be on your mind regarding AI, or anything else?
Let me know at garrisons@mcls.org.
By an overwhelming majority vote, our member representatives elected the proposed slate of board members to serve from Jan. 1, 2026 to Dec. 31, 2028. The elected slate includes:
Academic Library Representative (MI): Kendra Lake, North Central Michigan College
Academic Library Representative (IN): Josh Petrusa, Butler University Libraries
Public Library Representative (IN): Melissa Merida Foster, New Albany Floyd County Public Library
At-Large Library Representative (IN): Stephen Patton, Indiana State University
Special Library Representative (MI): Maria Ketcham, Detroit Institute of Arts Research Library & Archives
New and returning board members will join the current board for their annual planning retreat on Nov. 13-15. Congratulations!
The following library staff members have earned Certificates of Library Staff Development by attending workshops through MCLS!?
Basic Cataloging Certificate?
Jacqueline Cooper, IU Indianapolis Ruth Lilly Law Library, IN
Quintessa Gallinat, Manchester District Library, MI
Advanced Cataloging Certificate?
Jennifer Rasmussen, Northville District Library, MI
Timothy J. Streasick, University of Michigan – Dearborn, MI
Basic Essential Workplace Skills Certificate*?
Cynthia A. Glass, Vincennes University, IN
Jan King, Taylor University, IN
Denise L. Nees, Vincennes University, IN
Emily Nelson, Public Libraries of Saginaw, MI
Breezy Salisbury, The Floyd County Library, IN
Cyndi Schmidt, Orion Township Public Library, MI
Are you interested in obtaining your Certificate of Library Staff Development? For details, see our website.
*Essential Workplace Skills tutorials are free to MCLS members as a member benefit!
For questions, please email Gwen at training@mcls.org or call 517-220-9950.
Over the past year, Web of Science has introduced a range of enhancements designed to make it easier to discover, analyze, and share research. From improvements in search and navigation to new tools that support collaboration, transparency, and AI-powered insights, these updates are helping researchers and institutions work more efficiently and stay ahead in an evolving research landscape.
We welcome you and your colleagues to learn more about what’s new in a Web of Science webinar on Oct. 15 at 11 a.m. Eastern (10 a.m. Central). Deron Morgan will present these updates on behalf of Clarivate.
Register in advance for this meeting to receive the Zoom link.
Do you have questions about ConsortiaManager (CM) or your MCLS eResource invoices? If so, please join us for ConsortiaManager + Accounting Coffee Hour on Wednesday, Sept. 10 at 2 p.m. Eastern (1 p.m. Central). These informal sessions are not recorded, and most of the hour is reserved for questions and discussion. Our September Coffee Hour will include members of the Business and Operations team as well as members of the eLicensing and Collection Resources team.
Registrants will receive a confirmation email containing information about joining the Zoom meeting.
We look forward to seeing you there!
MCLS has negotiated transformative agreements with several publishers. These are typically multi-year agreements with a January subscription start date. Each publisher provides data to the participating institutions and/or to MCLS on publishing activity by institution. Some offer both a traditional “read” subscription option and the read and publish model through MCLS.
January 2026 journal renewals with transformative agreements include:
The MCLS eLicensing and Collection Resources team is open to negotiating additional transformative agreements, based on member libraries’ needs and interests. If you have questions, or if your library is interested in joining one of these agreements, contact us at services@mcls.org or 517-939-1382.
MCLS will hold its final Virtual Dialogue of 2025 on Thursday, Sept. 18 from 10:30 a.m.- noon Eastern (9:30-11 a.m. Central). All year, we’ve been bringing people in the library industry together to connect and engage around various topics related to the future of libraries. In September, we’ll be discussing the future of information access and how we can help people access information in times of disruption.
MCLS Virtual Dialogues are not courses or webinars but are opportunities to engage with others in the profession. Please plan to have your microphone enabled and camera on to participate. If you have any questions, please reach out at engagement@mcls.org.
We look forward to connecting with you!
Several MCLS staff members will present at conferences this fall. If you’re at any of these conferences, we hope to connect with you! Also, plan to stop by our booth and say “Hi!” in the vendor area at UPRLC, MLA, and ILF.
UPRLC Annual Conference
September 17-18 at Bay College, Iron Mountain
The Difference Is You Conference
September 19 at Indiana State Library
National Digital Stewardship Alliance Digital Preservation 2025 Conference
October 9-10, Online
Michigan Museums Association Annual Conference
October 13-15 in Lansing
Michigan Library Association Annual Conference
October 29-31 at the Lansing Center
Indiana Library Federation Annual Conference
November 9-11 at the Crowne Plaza Downtown Union Station, Indianapolis
This month I’m asking MCLS members for help: the MCLS Board of Directors will issue a brief 5-question survey focusing on the future to all of our member libraries on Wednesday, Sept. 3, and needs one response per member by Wednesday, Sept. 24. Please take this important survey to give our Board input they can use to update their vision and direction for MCLS in these challenging times for libraries.
MCLS member libraries are more than just members: they own MCLS as an organization. MCLS Board members represent and are accountable to the member/owners. They listen to the member/owners to learn what they value and what matters to them. They use what they learn to set and maintain a collective vision and direction for MCLS. In turn, the MCLS staff and I work to deliver on the Board’s vision in all we do for members and others where possible. I am accountable to the Board as Executive Director.
Our Board is issuing this survey now so they can have member/owners’ input ahead of their annual retreat in November, where they will focus on their vision and direction for MCLS.
Members, you can contact the 2025 MCLS Board members and learn about what they do and how on our website. I hope you’ll take their survey, and also find other ways to connect with them anytime to share your thoughts and ideas. Like me, they want to hear from you. It’s why our Board exists.
You may know that you can be part of the Board. If you want to get involved in helping set MCLS’s future direction, step forward when you see our annual call for Board nominations in early summer. Have questions about what the Board does? Ask a Board member you know, or me. We’re always looking for people who care about MCLS and want to see it empower libraries to achieve the extraordinary.
What do you value? What matters to you? What do you need? Let your Board members know, and let me know at garrisons@mcls.org.
Update: on July 31, 2025, the Senate Appropriations Committee approved the Labor, Health and Human Services, Education, and Related Agencies Subcommittee’s spending bill, which included $291,800,000 in total funding for IMLS (see pp. 329-330 for a budget activity breakdown for programs such as Grants to States).
With the U.S. Congress in recess until September, now is an important time to urge federal legislators to preserve federal funding for libraries nationwide via the Institute of Museum and Library Services’ (IMLS) Grants to States program. Grants to States provides funds for the purposes and priorities outlined in the Library Services and Technology Act (LSTA). State libraries each create a 5-year LSTA plan of programs they will fund using their annual Grants to States allocations. These include INSPIRE in Indiana and MeL in Michigan.
A July 15 American Libraries article explains the federal budget process briefly. Most years, Congress receives the executive branch’s budget request for the next fiscal year and House and Senate appropriations committees each respond by “marking up” spending bills that eventually help form the next year’s federal budget. The markup begins in several House and Senate appropriations subcommittees and then moves to the full committees.
The House and Senate each have a Labor, Health and Human Services, Education, and Related Agencies Subcommittee (abbreviated here as LHHS) that considers IMLS funding. Some House and Senate appropriations subcommittees started the markup process before the current recess. Based on information from a House contact, staff from the Association for Rural and Small Libraries (ARSL) and the Urban Libraries Council (ULC) stated in a July meeting I attended that the House LHHS Subcommittee will not begin the markup process on its federal FY2026 spending bill until September. This means that those who care about libraries’ federal funding have an opportunity to contact their federal legislators.
Indiana Congressman Frank Mrvan (D-IN-01) and Michigan Congressman John Moolenaar (R-MI-02) both serve on the U.S. House Appropriations Committee. Congressman Moolenaar also serves on the House’s LHHS Subcommittee. Senator Gary Peters (D-MI) serves on the U.S. Senate Appropriations Committee.
Libraries such as Traverse Area District Library (MI) and Crown Point Community Library (IN) have made good use of information and calls to action from organizations including the following to share the positive impact that federal funding makes for libraries’ communities through services such as MeL and INSPIRE:
In addition to the above and MLA’s new MeL bookmark and recent statewide polling data showing strong support for libraries statewide, the MCLS staff created a simple MeL information flyer about MeL’s impact using information from LM. All of the resources linked above are publicly available for anyone to use and share.
Have a question about, suggestion for, or correction to the information above? I’d be glad to hear from you at garrisons@mcls.org. In the meantime, I hope you will join me in encouraging others to express support for continuing federal funding for libraries, which delivers high return on investment for each dollar spent and significant cost savings for libraries, among many benefits to communities. LM reports that MeL eResources generate $26.96 in return value for each $1 spent, and provided $66,910,869.99 in cost avoidance for approximately 1,265 libraries of all types throughout Michigan, from a total investment of $2,481,885.12 for Michigan FY2024. LM’s 2024 Michigan Libraries Snapshot states that of its $4.8 million in federal funding for that year, LM used $3.7 million for MeL (plus $1.2 million in state funding).
Libraries provide great value for the investment the public makes in them, and this is an important moment to remind Congress of that.
This summer, Mittens will travel through RIDES to help the MeLCat libraries celebrate the 20th Anniversary of MeLCat.
Begin planning to take some photos of Mittens at your library. Be creative! Use the adventures of Flat Stanley and the Elf on the Shelf as inspiration. Instructions will be included. Some suggested activities with Mittens:
Use the hashtag #MittensLovesMeLCat to post about Mittens’ visit to your library’s social media, website, etc.
Mittens has a lot of libraries to visit, so send Mittens to the next library on the list within a couple of days. If you don’t have time when Mittens arrives, leave your library listed to route Mittens back to you. Feel free to share your photos, posts, or links via the MeLCat listserv. If you’d like to print your own Mittens, the files are available on MeL.org under the MeL Promotions Toolkit, along with the MeLCat 20th Anniversary logo.
Contact melcathelp@mcls.org if you have any questions.
The MeL project was made possible in part by the Institute of Museum and Library Services through the Library of Michigan.
MCLS’s Accounting and eLicensing & Collection Resources staff invite you to join us on Wednesday, Sept. 10 at 2 p.m. Eastern (1 p.m. Central) for an informal virtual drop-in session on Zoom. We’ll begin with brief updates and overviews. Most of the time will be reserved for discussion and any questions you may have about invoices or ConsortiaManager.
Registrants will receive a confirmation email containing information about joining the Zoom meeting. Coffee Hour sessions are not recorded.
We hope to see you there!
Register now
The following library staff members have earned Certificates of Library Staff Development by attending workshops through MCLS:
Basic Cataloging Certificate?
Annette Grover, Wells County Public Library, IN
Sarah Mominee, Novi Public Library, MI
Advanced Cataloging Certificate?
Annette Grover, Wells County Public Library, IN
Rebecca Kramb-Hubbard, Three Rivers Public Library, MI
Arom Park, Novi Public Library, MI
A. Elizabeth Wilson-Cotey, Valparaiso University, IN
Basic Essential Workplace Skills Certificate?
Colleen Prokop, St. Clair County Library System, MI
Are you interested in obtaining your Certificate of Library Staff Development? For details, see our website. Essential Workplace Skills tutorials are free to MCLS members as a member benefit! If you have any questions, please email Gwen at training@mcls.org or call 517-220-9950.
MCLS is excited to announce Ja’Kayla Sisson-Kilpatrick as our new Administrative Assistant. She came on board as a temp on May 19, 2025, and transitioned to permanent, full-time status on July 21. A member of our Business and Operations team, Ja’Kayla provides essential clerical support across multiple MCLS departments.
To help you get acquainted with Ja’Kayla, we asked her the following questions:
Q: What motivated you to take on this new role?
A: I moved from my hometown in Illinois to a new state and city; I was ready for a change in not only my environment but career as well.
Q: Do you have a favorite author, book, or genre?
A: My favorite authors are Alyssa Cole, Tiffany D. Jackson, and Sharon M. Draper. My favorite book is probably Tears of a Tiger from the Hazelwood High trilogy.
Q: Do you have any hidden talents or hobbies?
A: I’m not so great at it anymore, but I love drawing and painting!
Q: Who inspires you?
A: My mom truly inspires me; she’s gone through so much in her life and still manages to keep herself not only grounded but positive through it all and still shows up for people when needed.
Q: What is the best advice you have ever received?
A: The best advice I’ve ever received is to be kind and real with myself because I’m the only one who must deal with me and my thoughts 100% of the time.
Q: Do you volunteer?
A: Yes, I volunteer to help cater for/feed the homeless back in my old hometown almost every winter.
Q: Is there anything else you’d like the MCLS community to know about you?
A: I’m grateful to be here and am excited to start officially working with everyone!
The Indiana State Library (ISL) and the Library of Michigan (LM) provide critical funding from federal and state sources that power infrastructure supporting the work of hundreds of libraries. The Indiana Library Federation (ILF), the Michigan Library Association (MLA), and others have been advocating for support for ISL and LM. Both states’ legislatures have made choices in their fiscal year (FY) 2026 budget processes that have or may put state and local libraries and their programs at major risk.
There are hopeful signs for federal support for state libraries for the next year, though things still feel tenuous and there are huge questions about what happens after federal FY2025 and the state libraries’ FY2026. After the Institute of Museum and Library Services (IMLS) placed most staff members on administrative leave on March 14, Judge John G. McConnell issued a preliminary injunction on May 13 that prompted IMLS to return at least some staff to work. While it is unclear to many exactly how many IMLS staff have returned, ISL and LM have each heard from IMLS that they should expect to receive federal FY2025 IMLS Grants to States funds (LM’s amount is smaller than their FY2024 amount).
ISL and LM will use federal FY2025 dollars in their respective FYs 2026 (July 1-June 30 for ISL and October 1-September 30 for LM), and I anticipate that each will communicate how they will use their federal funds sometime later this summer. Libraries have been asking the state libraries and MCLS for more information about what to expect, and the state libraries have been working hard to plan and make decisions through major uncertainty.
At the state level, the state of Indiana cut ISL’s FY2026 budget by over 30%, prompting ISL to lay off 16 staff in June. In addition, new Indiana tax law reduces property tax funding for public libraries by eight figures beginning in 2026. While the Michigan State Senate’s FY2026 budget recommendation includes a $900,000 increase to state aid for public libraries, the Michigan State House FY2026 budget does not, and eliminates LM’s $5.6M IMLS Grants to States allocation. LM cannot use its federal funding without authorization from the Michigan legislature.
As Congress and the Michigan legislature continue through their difficult FY2026 budget discussions as of the time of this writing, many in the library community are under a great deal of stress about current and potential changes we’ll all face. While so much is unclear, I urge you to watch ILF’s and MLA’s websites for advocacy updates and helpful information on how you can help make the case to support funding for state and local libraries however possible.
As always, I also encourage you to reach out to our staff at MCLS with any questions you may have about how we may be able to help you maintain access to the critical information resources your communities rely on. Like the ISL and LM staff, MCLS’s staff also continue working hard to support libraries in these challenging times. Contact me anytime at garrisons@mcls.org with any questions or requests you may have.
In 2024, MeLCat began a project modernizing the INN-Reach software running MeLCat, as well as the DCB software, introducing a new, web-based client. The project kicked off with the central server update last July. In early 2025, we began modernizing the DCB servers, one at a time, and in late spring, we completed the final DCB server! It was a huge project with a lot of moving parts and changes.
We extend a big “THANK YOU” to all the MeLCat libraries for your patience and adaptability during this project. MeLCat continues to be a success largely due to the hard work at each participating library. As always, if you have any MeLCat questions or issues, please don’t hesitate to contact us at melcathelp@mcls.org.
The MeL project was made possible in part by the Institute of Museum and Library Services through the Library of Michigan.
Get ready for the 2025 MI OER Conference: Limitless Learning, Infinite Impact at Washtenaw Community College in Ann Arbor on Friday, Nov. 7, 2025. Registration opens July 15!
MCLS is pleased to partner with libraries and library organizations throughout Indiana and Michigan. One of these groups is the Michigan OER Network, a collaborative team representing multiple types of libraries and educational institutions, whose shared mission is to support the fair and equitable use of open educational resources (OER) for all learners in the state. They recently published the results of the 2024 Higher Ed Capacity Survey, which provides a benchmark of Open Educational Resources (OER) initiatives across Michigan’s higher education landscape, including 2-year, 4-year, and graduate schools. One of their other major initiatives is planning and hosting the MI OER Conference.
KEYNOTE SPEAKER AND PROGRAM
Our keynote speaker for the 2025 Conference will be Heather Blicher, Director of the Community College Consortium for OER (CCCOER) with Open Education Global. A passionate advocate for access, equity, and collaboration, Heather works to build community and empower practitioners as they drive the next wave of innovation in Open Education. Learn more about our keynote speaker, and about the conference program at mioer.org/events.
SCHOLARSHIPS AVAILABLE
Funding for conference scholarships is made possible through the generous support of our sponsors. Applications will be open July 15 through Oct. 10, and more information is available on the MI OER website.
SUBSCRIBE FOR UPDATES
Sign up for the MI OER Network email list to receive updates and communicate with fellow MI OER Network members.
The MI OER Network conference planning committee includes:
Chair: Molly Ledermann, Washtenaw Community College
Stacy Anderson, Ferris State University
Kendra Lake, North Central Michigan College
Haley Laurila, Henry Ford College
Beth Martin, Lake Michigan College
Kaylynn Mortensen, Schoolcraft College
Brian Newberry, Jackson College
Ashley Rosener, Grand Valley State University
Raya Samet, University of Michigan-Dearborn
Jill Sodt, Mott Community College
Michelle Westerdale, Washtenaw Community College
We are pleased to announce that the Indiana Library Federation (ILF) has selected Midwest Collaborative for Library Services (MCLS) to facilitate their upcoming strategic planning process. In addition, Indianapolis Public Library (IN) has invited MCLS to provide a staff day training for their Talent & Development Department this fall.
We are excited to work with both of you!
Is your library looking for library-specific consultants, presenters, or facilitators? MCLS can help! Visit our webpage to read more or contact us to request a quote.
The next date in MCLS’s popular Virtual Dialogue series is Thursday, July 17, from 10:30 a.m. to noon Eastern (9:30-11 a.m. Central). Our 2025 Virtual Dialogues are designed to provide opportunities for those in the library industry to connect and engage around various topics related to the future of libraries. This month we’ll discuss the Future of Engagement in Libraries, guiding the group through questions about various types of engagement – civic and community, relationships, and collaboration.
MCLS Virtual Dialogues are not courses or webinars, but rather opportunities to engage with others in the profession. Please plan to have your microphone enabled and camera on to participate.
Questions? Reach out to the Engagement, Consulting, & Training team at engagement@mcls.org.
We look forward to connecting with you!
On Monday, June 30, 2025, Indiana native and bestselling author John Green – known for The Fault in Our Stars and Looking for Alaska – will appear at the Pike Performing Arts Center for a one-night-only event focused on censorship, intellectual freedom, and the growing battle over access to books. Titled Censorship in the Trenches: John Green in Conversation with IN FREADOM…
The new semester of training workshops is now available! Visit the MCLS Store for the full summer/fall 2025 semester of training workshops and to see all workshops currently open for registration!
We are pleased to introduce Intermediate Rare Book Cataloging workshop taught by Tad Boehmer from Michigan State University. The Rare Book Cataloging: An Introduction workshop is always appreciated and well-attended, and many have requested a continuation with a more advanced course. Like the introductory course, Intermediate Rare Book Cataloging will be 3 days (6-hours). Learn more and register here.
In further response to requests from our class evaluations, we are offering an updated and expanded Electronic Serials Cataloging workshop. Taught by Steve Shadle from the University of Washington, the course will now be 3 days (6 hours). Learn more and register here.
Finally, the workshop previously titled Basics of RDA Conceptual Models is being updated and expanded. Its new title is Conceptual Models Underlying RDA, which better reflects the revised course content. This workshop will be 3 hours (1-day) and is taught by Andrea Morrison from Indiana University Bloomington. Learn more and register here.
Libraries today operate in complex environments, navigating evolving community expectations, and a growing set of unknowns. Whether large or small, urban or rural, all libraries share the common challenge of delivering high-quality services in a sustainable and impactful way. In this context, library consortia like the Midwest Collaborative for Library Services (MCLS) are an essential tool for cooperation, connection, and collaboration—one that not only strengthens individual libraries but also advances the greater library community’s shared goals.
A library consortium is a formal collaboration in which libraries unite to share resources, streamline services, negotiate better deals, and support each other’s missions. By working collectively, libraries can achieve goals that would be difficult or impossible to accomplish alone.
Library thought leader Lorcan Dempsey presents a power framework that argues that consortia are extremely beneficial to individual libraries and systems via their ability to scale capacity, learning, innovation, and influence. His 4-part blog series linked below touches on each element and helps define some of the less-discussed advantages of consortial affiliation.
With more than 630 member libraries of every type and size across Indiana and Michigan, MCLS provides a compelling example of Dempsey’s core framework elements.
Dempsey defines the first library consortium core power as scaling capacity, or increasing what individual libraries can accomplish by pooling resources and infrastructure. At MCLS, we do this through:
This capacity scaling allows MCLS members to extend their reach and improve services at a reasonable cost, which is essential in an era of constrained budgets.
Consortia create knowledge-based communities. Dempsey describes our role as scaling learning, or enabling continuous professional development and the exchange of expertise across institutions. MCLS nurtures this through:
We aim to promote collective learning, to ensure libraries stay agile and informed in a fast-changing field.
According to Dempsey, consortia are uniquely positioned to scale innovation because they can pilot new ideas, pool risk, and spread successful models more broadly. MCLS exemplifies this through programs like:
By connecting members with new tools, programs, and support, MCLS helps libraries experiment safely and adopt innovation faster.
Finally, Dempsey emphasizes the consortium’s role in scaling influence—amplifying the voice of libraries in policy, vendor negotiations, and public discourse. MCLS supports this by:
As a result, MCLS member libraries are not isolated, and are part of a larger, strategic network that commands attention and shapes the future of library service.
For more than a decade, hundreds of libraries have trusted MCLS to help them respond to change, innovate, and serve their communities more effectively. Libraries rely on us for cost savings and quality services, but MCLS is more than a service provider—we are also a member owned and governed organization, shaped by the very voices we strive to empower.
As Lorcan Dempsey observes, consortia deliver outcomes no single library can achieve alone. With our industry surrounded by rapid change and revolving unknowns, consortial collaboration is not simply helpful; it is essential. At MCLS, we want libraries to move beyond surviving change and actively engage in shaping it. To this end, MCLS staff leans into our vision: empowering libraries to achieve the extraordinary.
Have a question or an idea? Let’s talk. We’re here to listen and help. Visit mcls.org to learn more about our services, explore membership benefits, and see our current strategic plan. You can reach me directly at garrisons@mcls.org or 517-489-4071.
The MCLS Board of Directors Nominating Committee seeks nominations from the MCLS membership for the following Board openings for 2026-2028:
Each seat serves a three-year term, beginning Jan. 1, 2026, and expiring Dec. 31, 2028.
The Board meets four times per year: in February (via Zoom), and in May, August, and November (in person), alternating between Indiana and Michigan. The November meeting includes a Board orientation and a two-day strategy retreat to review activity of the previous year, assess trends, and determine strategic changes to MCLS’s services and offerings. Newly-elected Board members are asked to attend this year’s annual retreat, Nov. 13-15, 2025. MCLS reimburses Board members for all direct meeting expenses.
The MCLS Board follows the Policy Governance Model developed by John and Miriam Carver. New Board members will receive an orientation to Policy Governance the day prior to the Board retreat (Nov. 13).
MCLS’s members are also its owners. The Board represents your interests as owners. Through the nominating process, you have the opportunity to put forth the names of those who will define our Ends and Limits, both of which guide MCLS staff as they consider the products, programs, and services MCLS offers. The slate of candidates will be chosen from the nominations, voted on by the current Board of Directors in August, and presented to membership for election in early September. MCLS will announce Board election results in October.
To assist you in nominating candidates, please read Section 3 of the Board Policy Manual for an overview of the Board’s work and responsibilities. Under MCLS’s Bylaws Section 4.03, only designated Member Representatives or Alternates from MCLS member institutions are eligible to serve on the Board.
If you are interested in serving on the Board of Directors or wish to submit a nominee, please complete this form. The deadline for submission is 5 p.m. Eastern (4 p.m. Central) on Wednesday, July 2, 2025. If you would prefer to mail your nomination, please send it to: MCLS Nominating Committee, 1407 Rensen Street, Lansing, MI 48910-3657.
On May 27, MCLS welcomed James Orme as the new Financial Controller/Business Manager. James is a triple threat for this position as he has extensive management experience in libraries, finance, and HR. Staff is excited to have him on the management team, where he will oversee MCLS’s accounting, administrative, and business operations.
To help introduce James to the MCLS community, we engaged him in the following Q & A:
Q: Tell us a little about your background. How did you get started in libraries?
A: You could say I was destined for the library life—both of my parents are school librarians, so I practically grew up surrounded by books, Dewey Decimal classifications, and the occasional ‘shushing’ sound. Despite this early exposure, I didn’t realize how much I loved library work until I started working in one during my graduate program. I hold degrees in both Business Administration and Library Science, which means I can organize a collection and strategize a budget with equal enthusiasm. Over the years, I’ve worn different hats, Library Director at Great Lakes Christian College and HR and Business Manager at MSU, each giving me new insights and skills that I’m excited to bring to MCLS.
Q: What are you most excited to start working on?
A: I am eager to collaborate with my team and implement initiatives that drive meaningful change to MCLS’s business operations. My goal is to create a supportive environment where innovation and dedication translate into lasting positive outcomes.
Q: What do you like to do when you aren’t working?
A: When I’m not working, you’ll probably find me buried in a book, logging miles on a run, or venturing into the great outdoors. Hiking, camping, kayaking—basically anything that lets me pretend I’m starring in my own survival documentary (minus the actual danger, of course).
Q: Do you have a favorite author, book, or genre?
A: Picking a favorite is tough—I’m basically a literary wanderer, jumping between history, current events, nutrition, classic literature, philosophy, and travel. One day, I’m deep in an analysis of world-changing events, and the next, I’m trying to convince myself that kale is actually delicious. Classic literature lets me time-travel without needing a flux capacitor, philosophy keeps me pondering life’s biggest questions, and travel books fuel my ever-growing list of places I want to visit (and inevitably overpack for). So really, my reading habits are just an elaborate scheme to make me sound well-rounded at dinner parties.
Q: Do you have any hidden talents or hobbies?
A: I thrive in the art of making things from scratch—whether it’s bread, cheese, homebrew, or pasta, I like knowing that if civilization ever crumbled, I’d at least be able to keep myself fed. I also like distance hiking, as long as there’s a charming B&B waiting at the end of the trail, preferably with a hot meal and a pub nearby. Roughing it is great, but I firmly believe that adventure pairs best with a warm breakfast.
Q: What is the best advice you have ever received?
A: The best advice I ever received came from my 5th-grade math teacher, who boldly declared, ‘Mathematicians are lazy—they like finding the easiest way to solve their problems.’ At the time, it felt like a free pass to embrace my inner slacker, but as I got older, I realized the brilliance behind it. Efficiency isn’t about cutting corners; it’s about working smarter, not harder.
Q: What is one thing that instantly makes your day better?
A: MSU beating Michigan at absolutely anything. Whether it’s football, basketball, tiddlywinks—you name it, if the Spartans win, it’s a good day. Of course, my wife, a loyal Michigan fan, doesn’t quite agree with my enthusiasm. Needless to say, game days in our household are lively affairs, and I’ve learned to celebrate with just enough restraint to keep the peace…mostly.”
Q: Is there anything else you’d like the MCLS community to know about you?
A: I thrive on curiosity, humor, and a big, beautiful, balanced spreadsheet.
MCLS will be sending out a membership renewal email reminder to key library contacts (directors, billing contacts, and primary contacts) in early June. This email offers an opportunity to both respond with any changes to your membership and provide updated contact information ahead of our July 1 renewal date.
Invoices will be generated and emailed to your MCLS billing contact in mid-June. School libraries already received their invoices in May.
If your library’s director or billing contact has recently changed, please send updates to Gwen at membership@mcls.org as soon as possible. Thank you so much for being an MCLS member!
